Repository Public
1> [!CAUTION]2> **Deprecation notice:** This page is deprecated and will be removed. See the [What's new3> in Gemini 3.5 Flash](https://ai.google.dev/gemini-api/docs/whats-new-gemini-3.5) guide for the latest developer guidance, including migration instructions, prompting best practices, and an updated feature overview for all Gemini 3.x models.45Gemini 3 is our most intelligent model family to date, built on a foundation of6state-of-the-art reasoning. It is designed to bring any idea to life by7mastering agentic workflows, autonomous coding, and complex multimodal tasks.8This guide covers key features of the Gemini 3 model family and how to get the9most out of it.10[Try Gemini 3.1 Pro Preview](https://aistudio.google.com/prompts/new_chat?model=gemini-3.1-pro-preview) [Try Gemini 3 Flash Preview](https://aistudio.google.com/prompts/new_chat?model=gemini-3-flash-preview) [Try Gemini 3.1 Flash-Lite](https://aistudio.google.com/prompts/new_chat?model=gemini-3-flash-lite) [Try Nano Banana 2](https://aistudio.google.com/prompts/new_chat?model=gemini-3.1-flash-image-preview)1112Explore our [collection of Gemini 3 apps](https://aistudio.google.com/app/apps?source=showcase&showcaseTag=gemini-3) to13see how the model handles advanced reasoning, autonomous coding, and complex14multimodal tasks.1516Get started with a few lines of code:1718### Python1920 from google import genai2122 client = genai.Client()2324 response = client.models.generate_content(25 model="gemini-3.1-pro-preview",26 contents="Find the race condition in this multi-threaded C++ snippet: [code here]",27 )2829 print(response.text)3031### JavaScript3233 import { GoogleGenAI } from "@google/genai";3435 const ai = new GoogleGenAI({});3637 async function run() {38 const response = await ai.models.generateContent({39 model: "gemini-3.1-pro-preview",40 contents: "Find the race condition in this multi-threaded C++ snippet: [code here]",41 });4243 console.log(response.text);44 }4546 run();4748### REST4950 curl "https://generativelanguage.googleapis.com/v1beta/models/gemini-3.1-pro-preview:generateContent" \51 -H "x-goog-api-key: $GEMINI_API_KEY" \52 -H 'Content-Type: application/json' \53 -X POST \54 -d '{55 "contents": [{56 "parts": [{"text": "Find the race condition in this multi-threaded C++ snippet: [code here]"}]57 }]58 }'5960## Meet the Gemini 3 series6162Gemini 3.1 Pro is best for complex tasks that63require broad world knowledge and advanced reasoning across modalities.6465Gemini 3 Flash is our latest 3-series model, with Pro-level intelligence at the66speed and pricing of Flash.6768Nano Banana Pro (also known as Gemini 3 Pro Image) is our highest quality image69generation model, and Nano Banana 2 (also known as Gemini 3.1 Flash Image) is70the high-volume, high-efficiency, lower price-point equivalent.7172Gemini 3.1 Flash-Lite is our workhorse model built for cost-efficiency model and73high-volume tasks.7475| Model ID | Context Window (In / Out) | Knowledge Cutoff | Pricing (Input / Output)\* |76|---|---|---|---|77| **gemini-3.1-flash-lite** | 1M / 64k | Jan 2025 | $0.25 (text, image, video), $0.50 (audio) / $1.50 |78| **gemini-3.1-flash-image-preview** | 128k / 32k | Jan 2025 | $0.25 (Text Input) / $0.067 (Image Output)\*\* |79| **gemini-3.1-pro-preview** | 1M / 64k | Jan 2025 | $2 / $12 (\<200k tokens) $4 / $18 (\>200k tokens) |80| **gemini-3-flash-preview** | 1M / 64k | Jan 2025 | $0.50 / $3 |81| **gemini-3-pro-image-preview** | 65k / 32k | Jan 2025 | $2 (Text Input) / $0.134 (Image Output)\*\* |8283*\* Pricing is per 1 million tokens unless otherwise noted.*84*\*\* Image pricing varies by resolution. See the [pricing page](https://ai.google.dev/gemini-api/docs/pricing) for details.*8586For detailed limits, pricing, and additional information, see the87[models page](https://ai.google.dev/gemini-api/docs/models/gemini).8889## New API features in Gemini 39091Gemini 3 introduces new parameters designed to give developers more control over92latency, cost, and multimodal fidelity.9394### Thinking level9596Gemini 3 series models use dynamic thinking by default to reason through97prompts. You can use the `thinking_level` parameter, which controls the98**maximum** depth of the model's internal reasoning process before it produces a99response. Gemini 3 treats these levels as relative allowances for thinking100rather than strict token guarantees.101102If `thinking_level` is not specified, Gemini 3 will default to `high`. For103faster, lower-latency responses when complex reasoning isn't required, you can104constrain the model's thinking level to `low`.105106| Thinking Level | Gemini 3.1 Pro | Gemini 3.1 Flash-Lite | Gemini 3 Flash | Description |107|---|---|---|---|---|108| **`minimal`** | Not supported | Supported (Default) | Supported | Matches the "no thinking" setting for most queries. The model may think very minimally for complex coding tasks. Minimizes latency for chat or high throughput applications. Note, `minimal` does not guarantee that thinking is off. |109| **`low`** | Supported | Supported | Supported | Minimizes latency and cost. Best for simple instruction following, chat, or high-throughput applications. |110| **`medium`** | Supported | Supported | Supported | Balanced thinking for most tasks. |111| **`high`** | Supported (Default, Dynamic) | Supported (Dynamic) | Supported (Default, Dynamic) | Maximizes reasoning depth. The model may take significantly longer to reach a first (non thinking) output token, but the output will be more carefully reasoned. |112113### Python114115 from google import genai116 from google.genai import types117118 client = genai.Client()119120 response = client.models.generate_content(121 model="gemini-3.1-pro-preview",122 contents="How does AI work?",123 config=types.GenerateContentConfig(124 thinking_config=types.ThinkingConfig(thinking_level="low")125 ),126 )127128 print(response.text)129130### JavaScript131132 import { GoogleGenAI } from "@google/genai";133134 const ai = new GoogleGenAI({});135136 const response = await ai.models.generateContent({137 model: "gemini-3.1-pro-preview",138 contents: "How does AI work?",139 config: {140 thinkingConfig: {141 thinkingLevel: "low",142 }143 },144 });145146 console.log(response.text);147148### REST149150 curl "https://generativelanguage.googleapis.com/v1beta/models/gemini-3.1-pro-preview:generateContent" \151 -H "x-goog-api-key: $GEMINI_API_KEY" \152 -H 'Content-Type: application/json' \153 -X POST \154 -d '{155 "contents": [{156 "parts": [{"text": "How does AI work?"}]157 }],158 "generationConfig": {159 "thinkingConfig": {160 "thinkingLevel": "low"161 }162 }163 }'164165> [!IMPORTANT]166> **Important:** You cannot use both `thinking_level` and the legacy `thinking_budget` parameter in the same request. Doing so will return a 400 error.167168### Media resolution169170Gemini 3 introduces granular control over multimodal vision processing using the171`media_resolution` parameter. Higher resolutions improve the model's ability to172read fine text or identify small details, but increase token usage and latency.173The `media_resolution` parameter determines the **maximum number of tokens174allocated per input image or video frame.**175176You can now set the resolution to `media_resolution_low`,177`media_resolution_medium`, `media_resolution_high`, or178`media_resolution_ultra_high` per individual media part or globally (via179`generation_config`, global not available for ultra high). If unspecified, the180model uses optimal defaults based on the media type.181182**Recommended settings**183184| Media Type | Recommended Setting | Max Tokens | Usage Guidance |185|---|---|---|---|186| **Images** | `media_resolution_high` | 1120 | Recommended for most image analysis tasks to ensure maximum quality. |187| **PDFs** | `media_resolution_medium` | 560 | Optimal for document understanding; quality typically saturates at `medium`. Increasing to `high` rarely improves OCR results for standard documents. |188| **Video** (General) | `media_resolution_low` (or `media_resolution_medium`) | 70 (per frame) | **Note:** For video, `low` and `medium` settings are treated identically (70 tokens) to optimize context usage. This is sufficient for most action recognition and description tasks. |189| **Video** (Text-heavy) | `media_resolution_high` | 280 (per frame) | Required only when the use case involves reading dense text (OCR) or small details within video frames. |190191> [!NOTE]192> **Note:** The `media_resolution` parameter maps to different token counts depending on the input type. While images scale linearly (`media_resolution_low`: 280, `media_resolution_medium`: 560, `media_resolution_high`: 1120), Video is compressed more aggressively. For Video, both `media_resolution_low` and `media_resolution_medium` are capped at 70 tokens per frame, and `media_resolution_high` is capped at 280 tokens. See the full details on the [Media resolution](https://ai.google.dev/gemini-api/docs/media-resolution#token-counts) page.193194### Python195196 from google import genai197 from google.genai import types198 import base64199200 # The media_resolution parameter is available in the v1beta API version.201 client = genai.Client(http_options={'api_version': 'v1beta'})202203 response = client.models.generate_content(204 model="gemini-3.1-pro-preview",205 contents=[206 types.Content(207 parts=[208 types.Part(text="What is in this image?"),209 types.Part(210 inline_data=types.Blob(211 mime_type="image/jpeg",212 data=base64.b64decode("..."),213 ),214 media_resolution={"level": "media_resolution_high"}215 )216 ]217 )218 ]219 )220221 print(response.text)222223### JavaScript224225 import { GoogleGenAI } from "@google/genai";226227 // The media_resolution parameter is available in the v1beta API version.228 const ai = new GoogleGenAI({ apiVersion: "v1beta" });229230 async function run() {231 const response = await ai.models.generateContent({232 model: "gemini-3.1-pro-preview",233 contents: [234 {235 parts: [236 { text: "What is in this image?" },237 {238 inlineData: {239 mimeType: "image/jpeg",240 data: "...",241 },242 mediaResolution: {243 level: "media_resolution_high"244 }245 }246 ]247 }248 ]249 });250251 console.log(response.text);252 }253254 run();255256### REST257258 curl "https://generativelanguage.googleapis.com/v1beta/models/gemini-3.1-pro-preview:generateContent" \259 -H "x-goog-api-key: $GEMINI_API_KEY" \260 -H 'Content-Type: application/json' \261 -X POST \262 -d '{263 "contents": [{264 "parts": [265 { "text": "What is in this image?" },266 {267 "inlineData": {268 "mimeType": "image/jpeg",269 "data": "..."270 },271 "mediaResolution": {272 "level": "media_resolution_high"273 }274 }275 ]276 }]277 }'278279### Temperature280281For all Gemini 3 models, we strongly recommend keeping the temperature parameter282at its default value of `1.0`.283284While previous models often benefited from tuning temperature to control285creativity versus determinism, Gemini 3's reasoning capabilities are optimized286for the default setting. Changing the temperature (setting it below 1.0) may287lead to unexpected behavior, such as looping or degraded performance,288particularly in complex mathematical or reasoning tasks.289290### Thought signatures291292Gemini 3 uses [Thought signatures](https://ai.google.dev/gemini-api/docs/thought-signatures) to293maintain reasoning context across API calls. These signatures are encrypted294representations of the model's internal thought process. To ensure the model295maintains its reasoning capabilities you must return these signatures back to296the model in your request exactly as they were received:297298- **Function Calling (Strict):** The API enforces strict validation on the299 "Current Turn". Missing signatures will result in a 400 error.300301 > [!NOTE]302 > **Note:** Circulation of thought signatures is required even when [thinking level](https://ai.google.dev/gemini-api/docs/generate-content/gemini-3#thinking_level) is set to `minimal` for Gemini 3 Flash.303304- **Text/Chat:** Validation is not strictly enforced, but omitting signatures will degrade the model's reasoning and answer quality.305306- **Image generation/editing (Strict)** : The API enforces strict validation on all Model parts including a `thoughtSignature`. Missing signatures will result in a 400 error.307308> [!TIP]309> **Success:** If you use the [official SDKs (Python, Node, Java)](https://ai.google.dev/gemini-api/docs/function-calling?example=meeting#thinking) and standard chat history, Thought Signatures are handled automatically. You do not need to manually manage these fields.310311#### Function calling (strict validation)312313When Gemini generates a `functionCall`, it relies on the `thoughtSignature` to314process the tool's output correctly in the next turn. The "Current Turn"315includes all Model (`functionCall`) and User (`functionResponse`) steps that316occurred since the last standard **User** `text` message.317318- **Single Function Call:** The `functionCall` part contains a signature. You must return it.319- **Parallel Function Calls:** Only the first `functionCall` part in the list will contain the signature. You must return the parts in the exact order received.320- **Multi-Step (Sequential):** If the model calls a tool, receives a result, and calls *another* tool (within the same turn), **both** function calls have signatures. You must return **all** accumulated signatures in the history.321322#### Text and streaming323324For standard chat or text generation, the presence of a signature is not325guaranteed.326327- **Non-Streaming** : The final content part of the response may contain a `thoughtSignature`, though it is not always present. If one is returned, you should send it back to maintain best performance.328- **Streaming**: If a signature is generated, it may arrive in a final chunk that contains an empty text part. Ensure your stream parser checks for signatures even if the text field is empty.329330#### Image generation and editing331332For `gemini-3-pro-image-preview` and `gemini-3.1-flash-image-preview`, thought333signatures are critical for334conversational editing. When you ask the model to modify an image it relies on335the `thoughtSignature` from the previous turn to understand the composition and336logic of the original image.337338- **Editing:** Signatures are guaranteed on the first part after the thoughts of the response (`text` or `inlineData`) and on every subsequent `inlineData` part. You must return all of these signatures to avoid errors.339340#### Code examples341342#### Multi-step Function Calling (Sequential)343344The user asks a question requiring two separate steps (Check Flight -\> Book Taxi) in one turn. 345346347**Step 1: Model calls Flight Tool.** 348349The model returns a signature `<Sig_A>`350351```java352// Model Response (Turn 1, Step 1)353 {354 "role": "model",355 "parts": [356 {357 "functionCall": { "name": "check_flight", "args": {...} },358 "thoughtSignature": "<Sig_A>" // SAVE THIS359 }360 ]361 }362```363364**Step 2: User sends Flight Result** 365366We must send back `<Sig_A>` to keep the model's train of thought.367368```java369// User Request (Turn 1, Step 2)370[371 { "role": "user", "parts": [{ "text": "Check flight AA100..." }] },372 {373 "role": "model",374 "parts": [375 { 376 "functionCall": { "name": "check_flight", "args": {...} },377 "thoughtSignature": "<Sig_A>" // REQUIRED378 }379 ]380 },381 { "role": "user", "parts": [{ "functionResponse": { "name": "check_flight", "response": {...} } }] }382]383```384385**Step 3: Model calls Taxi Tool** 386387The model remembers the flight delay via `<Sig_A>` and now decides to book a taxi. It generates a *new* signature `<Sig_B>`.388389```java390// Model Response (Turn 1, Step 3)391{392 "role": "model",393 "parts": [394 {395 "functionCall": { "name": "book_taxi", "args": {...} },396 "thoughtSignature": "<Sig_B>" // SAVE THIS397 }398 ]399}400```401402**Step 4: User sends Taxi Result** 403404To complete the turn, you must send back the entire chain: `<Sig_A>` AND `<Sig_B>`.405406```java407// User Request (Turn 1, Step 4)408[409 // ... previous history ...410 { 411 "role": "model", 412 "parts": [413 { "functionCall": { "name": "check_flight", ... }, "thoughtSignature": "<Sig_A>" }414 ]415 },416 { "role": "user", "parts": [{ "functionResponse": {...} }] },417 { 418 "role": "model", 419 "parts": [420 { "functionCall": { "name": "book_taxi", ... }, "thoughtSignature": "<Sig_B>" }421 ]422 },423 { "role": "user", "parts": [{ "functionResponse": {...} }] }424]425```426427#### Parallel Function Calling428429The user asks: "Check the weather in Paris and London." The model returns two function calls in one response.430431```java432// User Request (Sending Parallel Results)433[434 {435 "role": "user",436 "parts": [437 { "text": "Check the weather in Paris and London." }438 ]439 },440 {441 "role": "model",442 "parts": [443 // 1. First Function Call has the signature444 {445 "functionCall": { "name": "check_weather", "args": { "city": "Paris" } },446 "thoughtSignature": "<Signature_A>" 447 },448 // 2. Subsequent parallel calls DO NOT have signatures449 {450 "functionCall": { "name": "check_weather", "args": { "city": "London" } }451 } 452 ]453 },454 {455 "role": "user",456 "parts": [457 // 3. Function Responses are grouped together in the next block458 {459 "functionResponse": { "name": "check_weather", "response": { "temp": "15C" } }460 },461 {462 "functionResponse": { "name": "check_weather", "response": { "temp": "12C" } }463 }464 ]465 }466]467```468469#### Text/In-Context Reasoning (No Validation)470471The user asks a question that requires in-context reasoning without external tools. While not strictly validated, including the signature helps the model maintain the reasoning chain for follow-up questions.472473```java474// User Request (Follow-up question)475[476 {477 "role": "user",478 "parts": [{ "text": "What are the risks of this investment?" }]479 },480 {481 "role": "model",482 "parts": [483 {484 "text": "I need to calculate the risk step-by-step. First, I'll look at volatility...",485 "thoughtSignature": "<Signature_C>" // Recommended to include486 }487 ]488 },489 {490 "role": "user",491 "parts": [{ "text": "Summarize that in one sentence." }]492 }493]494```495496#### Image Generation \& Editing497498For image generation, signatures are strictly validated. They appear on the **first part** (text or image) and **all subsequent image parts**. All must be returned in the next turn.499500```java501// Model Response (Turn 1)502{503 "role": "model",504 "parts": [505 // 1. First part ALWAYS has a signature (even if text)506 {507 "text": "I will generate a cyberpunk city...",508 "thoughtSignature": "<Signature_D>"509 },510 // 2. ALL InlineData (Image) parts ALWAYS have signatures511 {512 "inlineData": { ... }, 513 "thoughtSignature": "<Signature_E>"514 },515 ]516}517518// User Request (Turn 2 - Requesting an Edit)519{520 "contents": [521 // History must include ALL signatures received522 {523 "role": "user",524 "parts": [{ "text": "Generate a cyberpunk city" }]525 },526 {527 "role": "model",528 "parts": [529 { "text": "...", "thoughtSignature": "<Signature_D>" },530 { "inlineData": "...", "thoughtSignature": "<Signature_E>" },531 ]532 },533 // New User Prompt534 {535 "role": "user",536 "parts": [{ "text": "Make it daytime." }]537 }538 ]539}540```541542#### Migrating from other models543544If you are transferring a conversation trace from another model (e.g., Gemini5452.5) or injecting a custom function call that was not generated by Gemini 3,546you will not have a valid signature.547548To bypass strict validation in these specific scenarios, populate the field with549this specific dummy string: `"thoughtSignature": "context_engineering_is_the_way550to_go"`551552### Structured Outputs with tools553554Gemini 3 models allow you to combine [Structured Outputs](https://ai.google.dev/gemini-api/docs/structured-output) with built-in tools, including555[Grounding with Google Search](https://ai.google.dev/gemini-api/docs/google-search), [URL Context](https://ai.google.dev/gemini-api/docs/url-context), [Code Execution](https://ai.google.dev/gemini-api/docs/code-execution), and [Function Calling](https://ai.google.dev/gemini-api/docs/function-calling).556557### Python558559 from google import genai560 from google.genai import types561 from pydantic import BaseModel, Field562 from typing import List563564 class MatchResult(BaseModel):565 winner: str = Field(description="The name of the winner.")566 final_match_score: str = Field(description="The final match score.")567 scorers: List[str] = Field(description="The name of the scorer.")568569 client = genai.Client()570571 response = client.models.generate_content(572 model="gemini-3.1-pro-preview",573 contents="Search for all details for the latest Euro.",574 config={575 "tools": [576 {"google_search": {}},577 {"url_context": {}}578 ],579 "response_format": {"text": {"mime_type": "application/json", "schema": MatchResult.model_json_schema()}},580 }, 581 )582583 result = MatchResult.model_validate_json(response.text)584 print(result)585586### JavaScript587588 import { GoogleGenAI } from "@google/genai";589 import { z } from "zod";590 import { zodToJsonSchema } from "zod-to-json-schema";591592 const ai = new GoogleGenAI({});593594 const matchSchema = z.object({595 winner: z.string().describe("The name of the winner."),596 final_match_score: z.string().describe("The final score."),597 scorers: z.array(z.string()).describe("The name of the scorer.")598 });599600 async function run() {601 const response = await ai.models.generateContent({602 model: "gemini-3.1-pro-preview",603 contents: "Search for all details for the latest Euro.",604 config: {605 tools: [606 { googleSearch: {} },607 { urlContext: {} }608 ],609 responseFormat: { text: { mimeType: "application/json", schema: zodToJsonSchema(matchSchema) } },610 },611 });612613 const match = matchSchema.parse(JSON.parse(response.text));614 console.log(match);615 }616617 run();618619### REST620621 curl "https://generativelanguage.googleapis.com/v1beta/models/gemini-3.1-pro-preview:generateContent" \622 -H "x-goog-api-key: $GEMINI_API_KEY" \623 -H 'Content-Type: application/json' \624 -X POST \625 -d '{626 "contents": [{627 "parts": [{"text": "Search for all details for the latest Euro."}]628 }],629 "tools": [630 {"googleSearch": {}},631 {"urlContext": {}}632 ],633 "generationConfig": {634 "responseFormat": {635 "text": {636 "mimeType": "application/json",637 "schema": {638 "type": "object",639 "properties": {640 "winner": {"type": "string", "description": "The name of the winner."},641 "final_match_score": {"type": "string", "description": "The final score."},642 "scorers": {643 "type": "array",644 "items": {"type": "string"},645 "description": "The name of the scorer."646 }647 }648 }649 },650 "required": ["winner", "final_match_score", "scorers"]651 }652 }653 }'654655### Image generation656657Gemini 3.1 Flash Image and Gemini 3 Pro Image let you generate and edit images658from text prompts. It uses659reasoning to "think" through a prompt and can retrieve real-time data---such as660weather forecasts or stock charts---before using [Google Search](https://ai.google.dev/gemini-api/docs/google-search) grounding before generating high-fidelity661images.662663**New \& improved capabilities:**664665- **4K \& text rendering:** Generate sharp, legible text and diagrams with up to 2K and 4K resolutions.666- **Grounded generation:** Use the `google_search` tool to verify facts and generate imagery based on real-world information. Grounding with Google *Image* Search available for Gemini 3.1 Flash Image.667- **Conversational editing:** Multi-turn image editing by simply asking for changes (e.g., "Make the background a sunset"). This workflow relies on **Thought Signatures** to preserve visual context between turns.668669For complete details on aspect ratios, editing workflows, and configuration670options, see the [Image Generation guide](https://ai.google.dev/gemini-api/docs/image-generation).671672### Python673674 from google import genai675 from google.genai import types676677 client = genai.Client()678679 response = client.models.generate_content(680 model="gemini-3-pro-image-preview",681 contents="Generate an infographic of the current weather in Tokyo.",682 config=types.GenerateContentConfig(683 tools=[{"google_search": {}}],684 response_format={"image": {"aspect_ratio": "16:9", "image_size": "4K"}}685 )686 )687688 image_parts = [part for part in response.parts if part.inline_data]689690 if image_parts:691 image = image_parts[0].as_image()692 image.save('weather_tokyo.png')693 image.show()694695### JavaScript696697 import { GoogleGenAI } from "@google/genai";698 import * as fs from "node:fs";699700 const ai = new GoogleGenAI({});701702 async function run() {703 const response = await ai.models.generateContent({704 model: "gemini-3-pro-image-preview",705 contents: "Generate a visualization of the current weather in Tokyo.",706 config: {707 tools: [{ googleSearch: {} }],708 responseFormat: {709 image: {710 aspectRatio: "16:9",711 imageSize: "4K"712 }713 }714 }715 });716717 for (const part of response.candidates[0].content.parts) {718 if (part.inlineData) {719 const imageData = part.inlineData.data;720 const buffer = Buffer.from(imageData, "base64");721 fs.writeFileSync("weather_tokyo.png", buffer);722 }723 }724 }725726 run();727728### REST729730 curl "https://generativelanguage.googleapis.com/v1beta/models/gemini-3-pro-image-preview:generateContent" \731 -H "x-goog-api-key: $GEMINI_API_KEY" \732 -H 'Content-Type: application/json' \733 -X POST \734 -d '{735 "contents": [{736 "parts": [{"text": "Generate a visualization of the current weather in Tokyo."}]737 }],738 "tools": [{"googleSearch": {}}],739 "generationConfig": {740 "responseFormat": {741 "image": {742 "aspectRatio": "16:9",743 "imageSize": "4K"744 }745 }746 }747 }'748749**Example Response**750751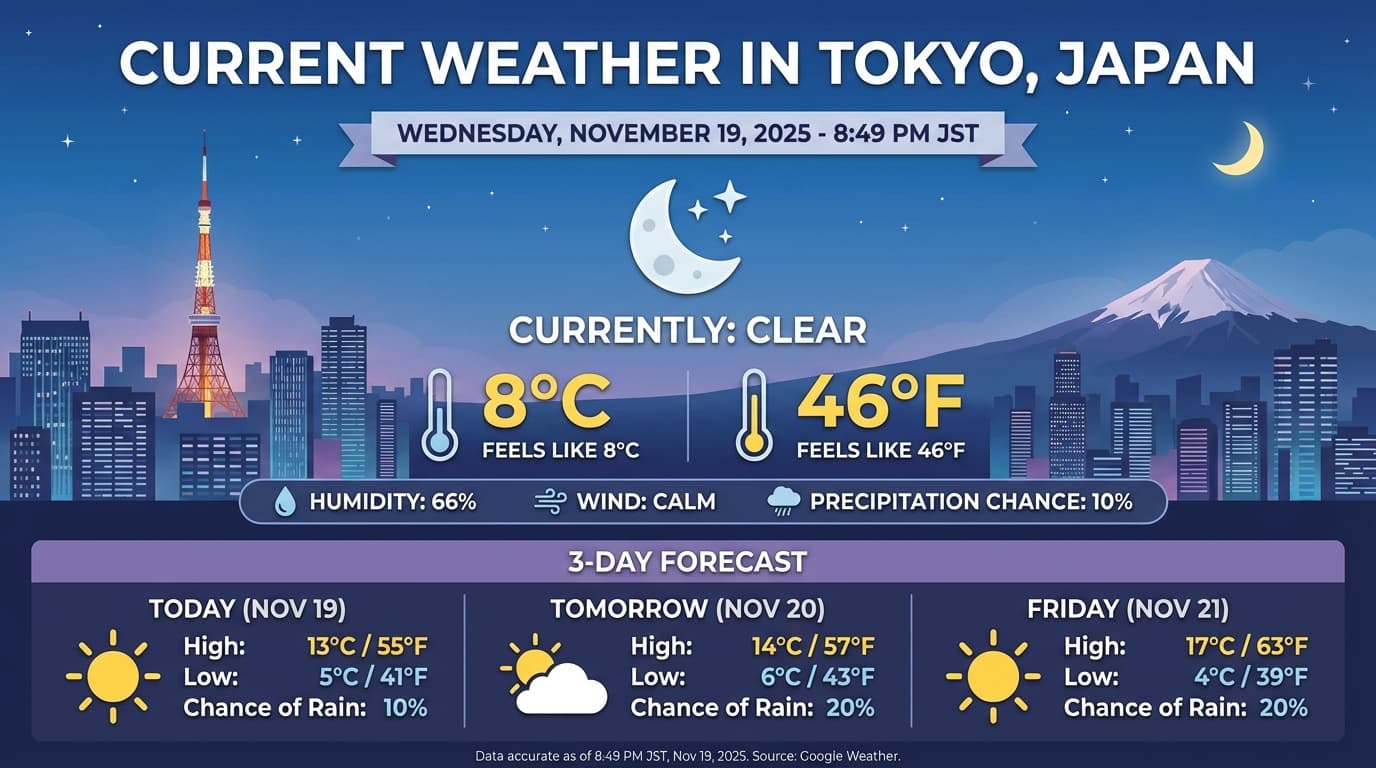752753### Code Execution with images754755Gemini 3 Flash can treat vision as an active investigation, not just a static756glance. By combining reasoning with [code execution](https://ai.google.dev/gemini-api/docs/code-execution), the model formulates a plan, then writes and757executes Python code to zoom in, crop, annotate, or otherwise manipulate images758step-by-step to visually ground its answers.759760**Use cases:**761762- **Zoom and inspect:** The model implicitly detects when details are too small (e.g., reading a distant gauge or serial number) and writes code to crop and re-examine the area at higher resolution.763- **Visual math and plotting:** The model can run multi-step calculations using code (e.g., summing line items on a receipt, or generating a Matplotlib chart from extracted data).764- **Image annotation:** The model can draw arrows, bounding boxes, or other annotations directly onto images to answer spatial questions like "Where should this item go?".765766To enable visual thinking, configure [Code Execution](https://ai.google.dev/gemini-api/docs/code-execution) as a tool. The model will automatically use767code to manipulate images when needed.768769### Python770771 from google import genai772 from google.genai import types773 import requests774 from PIL import Image775 import io776777 image_path = "https://goo.gle/instrument-img"778 image_bytes = requests.get(image_path).content779 image = types.Part.from_bytes(data=image_bytes, mime_type="image/jpeg")780781 client = genai.Client()782783 response = client.models.generate_content(784 model="gemini-3-flash-preview",785 contents=[786 image,787 "Zoom into the expression pedals and tell me how many pedals are there?"788 ],789 config=types.GenerateContentConfig(790 tools=[types.Tool(code_execution=types.ToolCodeExecution)]791 ),792 )793794 for part in response.candidates[0].content.parts:795 if part.text is not None:796 print(part.text)797 if part.executable_code is not None:798 print(part.executable_code.code)799 if part.code_execution_result is not None:800 print(part.code_execution_result.output)801 if part.as_image() is not None:802 display(Image.open(io.BytesIO(part.as_image().image_bytes)))803804### JavaScript805806 import { GoogleGenAI } from "@google/genai";807808 const ai = new GoogleGenAI({});809810 async function main() {811 const imageUrl = "https://goo.gle/instrument-img";812 const response = await fetch(imageUrl);813 const imageArrayBuffer = await response.arrayBuffer();814 const base64ImageData = Buffer.from(imageArrayBuffer).toString("base64");815816 const result = await ai.models.generateContent({817 model: "gemini-3-flash-preview",818 contents: [819 {820 inlineData: {821 mimeType: "image/jpeg",822 data: base64ImageData,823 },824 },825 {826 text: "Zoom into the expression pedals and tell me how many pedals are there?",827 },828 ],829 config: {830 tools: [{ codeExecution: {} }],831 },832 });833834 for (const part of result.candidates[0].content.parts) {835 if (part.text) {836 console.log("Text:", part.text);837 }838 if (part.executableCode) {839 console.log("Code:", part.executableCode.code);840 }841 if (part.codeExecutionResult) {842 console.log("Output:", part.codeExecutionResult.output);843 }844 }845 }846847 main();848849### REST850851 IMG_URL="https://goo.gle/instrument-img"852 MODEL="gemini-3-flash-preview"853854 MIME_TYPE=$(curl -sIL "$IMG_URL" | grep -i '^content-type:' | awk -F ': ' '{print $2}' | sed 's/\r$//' | head -n 1)855 if [[ -z "$MIME_TYPE" || ! "$MIME_TYPE" == image/* ]]; then856 MIME_TYPE="image/jpeg"857 fi858859 if [[ "$(uname)" == "Darwin" ]]; then860 IMAGE_B64=$(curl -sL "$IMG_URL" | base64 -b 0)861 elif [[ "$(base64 --version 2>&1)" = *"FreeBSD"* ]]; then862 IMAGE_B64=$(curl -sL "$IMG_URL" | base64)863 else864 IMAGE_B64=$(curl -sL "$IMG_URL" | base64 -w0)865 fi866867 curl "https://generativelanguage.googleapis.com/v1beta/models/$MODEL:generateContent" \868 -H "x-goog-api-key: $GEMINI_API_KEY" \869 -H 'Content-Type: application/json' \870 -X POST \871 -d '{872 "contents": [{873 "parts":[874 {875 "inline_data": {876 "mime_type":"'"$MIME_TYPE"'",877 "data": "'"$IMAGE_B64"'"878 }879 },880 {"text": "Zoom into the expression pedals and tell me how many pedals are there?"}881 ]882 }],883 "tools": [{"code_execution": {}}]884 }'885886For more details on code execution with images, see [Code Execution](https://ai.google.dev/gemini-api/docs/code-execution#images).887888### Multimodal function responses889890[Multimodal function calling](https://ai.google.dev/gemini-api/docs/function-calling#multimodal)891allows users to have function responses containing892multimodal objects allowing for improved utilization of function calling893capabilities of the model. Standard function calling only supports text-based894function responses:895896### Python897898 from google import genai899 from google.genai import types900901 import requests902903 client = genai.Client()904905 # This is a manual, two turn multimodal function calling workflow:906907 # 1. Define the function tool908 get_image_declaration = types.FunctionDeclaration(909 name="get_image",910 description="Retrieves the image file reference for a specific order item.",911 parameters={912 "type": "object",913 "properties": {914 "item_name": {915 "type": "string",916 "description": "The name or description of the item ordered (e.g., 'instrument')."917 }918 },919 "required": ["item_name"],920 },921 )922 tool_config = types.Tool(function_declarations=[get_image_declaration])923924 # 2. Send a message that triggers the tool925 prompt = "Show me the instrument I ordered last month."926 response_1 = client.models.generate_content(927 model="gemini-3-flash-preview",928 contents=[prompt],929 config=types.GenerateContentConfig(930 tools=[tool_config],931 )932 )933934 # 3. Handle the function call935 function_call = response_1.function_calls[0]936 requested_item = function_call.args["item_name"]937 print(f"Model wants to call: {function_call.name}")938939 # Execute your tool (e.g., call an API)940 # (This is a mock response for the example)941 print(f"Calling external tool for: {requested_item}")942943 function_response_data = {944 "image_ref": {"$ref": "instrument.jpg"},945 }946 image_path = "https://goo.gle/instrument-img"947 image_bytes = requests.get(image_path).content948 function_response_multimodal_data = types.FunctionResponsePart(949 inline_data=types.FunctionResponseBlob(950 mime_type="image/jpeg",951 display_name="instrument.jpg",952 data=image_bytes,953 )954 )955956 # 4. Send the tool's result back957 # Append this turn's messages to history for a final response.958 history = [959 types.Content(role="user", parts=[types.Part(text=prompt)]),960 response_1.candidates[0].content,961 types.Content(962 role="user",963 parts=[964 types.Part.from_function_response(965 name=function_call.name,966 response=function_response_data,967 parts=[function_response_multimodal_data]968 )969 ],970 )971 ]972973 response_2 = client.models.generate_content(974 model="gemini-3-flash-preview",975 contents=history,976 config=types.GenerateContentConfig(977 tools=[tool_config],978 thinking_config=types.ThinkingConfig(include_thoughts=True)979 ),980 )981982 print(f"\nFinal model response: {response_2.text}")983984### JavaScript985986 import { GoogleGenAI, Type } from '@google/genai';987988 const client = new GoogleGenAI({ apiKey: process.env.GEMINI_API_KEY });989990 // This is a manual, two turn multimodal function calling workflow:991 // 1. Define the function tool992 const getImageDeclaration = {993 name: 'get_image',994 description: 'Retrieves the image file reference for a specific order item.',995 parameters: {996 type: Type.OBJECT,997 properties: {998 item_name: {999 type: Type.STRING,1000 description: "The name or description of the item ordered (e.g., 'instrument').",1001 },1002 },1003 required: ['item_name'],1004 },1005 };10061007 const toolConfig = {1008 functionDeclarations: [getImageDeclaration],1009 };10101011 // 2. Send a message that triggers the tool1012 const prompt = 'Show me the instrument I ordered last month.';1013 const response1 = await client.models.generateContent({1014 model: 'gemini-3-flash-preview',1015 contents: prompt,1016 config: {1017 tools: [toolConfig],1018 },1019 });10201021 // 3. Handle the function call1022 const functionCall = response1.functionCalls[0];1023 const requestedItem = functionCall.args.item_name;1024 console.log(`Model wants to call: ${functionCall.name}`);10251026 // Execute your tool (e.g., call an API)1027 // (This is a mock response for the example)1028 console.log(`Calling external tool for: ${requestedItem}`);10291030 const functionResponseData = {1031 image_ref: { $ref: 'instrument.jpg' },1032 };10331034 const imageUrl = "https://goo.gle/instrument-img";1035 const response = await fetch(imageUrl);1036 const imageArrayBuffer = await response.arrayBuffer();1037 const base64ImageData = Buffer.from(imageArrayBuffer).toString('base64');10381039 const functionResponseMultimodalData = {1040 inlineData: {1041 mimeType: 'image/jpeg',1042 displayName: 'instrument.jpg',1043 data: base64ImageData,1044 },1045 };10461047 // 4. Send the tool's result back1048 // Append this turn's messages to history for a final response.1049 const history = [1050 { role: 'user', parts: [{ text: prompt }] },1051 response1.candidates[0].content,1052 {1053 role: 'tool',1054 parts: [1055 {1056 functionResponse: {1057 name: functionCall.name,1058 response: functionResponseData,1059 parts: [functionResponseMultimodalData],1060 },1061 },1062 ],1063 },1064 ];10651066 const response2 = await client.models.generateContent({1067 model: 'gemini-3-flash-preview',1068 contents: history,1069 config: {1070 tools: [toolConfig],1071 thinkingConfig: { includeThoughts: true },1072 },1073 });10741075 console.log(`\nFinal model response: ${response2.text}`);10761077### REST10781079 IMG_URL="https://goo.gle/instrument-img"10801081 MIME_TYPE=$(curl -sIL "$IMG_URL" | grep -i '^content-type:' | awk -F ': ' '{print $2}' | sed 's/\r$//' | head -n 1)1082 if [[ -z "$MIME_TYPE" || ! "$MIME_TYPE" == image/* ]]; then1083 MIME_TYPE="image/jpeg"1084 fi10851086 # Check for macOS1087 if [[ "$(uname)" == "Darwin" ]]; then1088 IMAGE_B64=$(curl -sL "$IMG_URL" | base64 -b 0)1089 elif [[ "$(base64 --version 2>&1)" = *"FreeBSD"* ]]; then1090 IMAGE_B64=$(curl -sL "$IMG_URL" | base64)1091 else1092 IMAGE_B64=$(curl -sL "$IMG_URL" | base64 -w0)1093 fi10941095 curl "https://generativelanguage.googleapis.com/v1beta/models/gemini-3-flash-preview:generateContent" \1096 -H "x-goog-api-key: $GEMINI_API_KEY" \1097 -H 'Content-Type: application/json' \1098 -X POST \1099 -d '{1100 "contents": [1101 ...,1102 {1103 "role": "user",1104 "parts": [1105 {1106 "functionResponse": {1107 "name": "get_image",1108 "response": {1109 "image_ref": {1110 "$ref": "instrument.jpg"1111 }1112 },1113 "parts": [1114 {1115 "inlineData": {1116 "displayName": "instrument.jpg",1117 "mimeType":"'"$MIME_TYPE"'",1118 "data": "'"$IMAGE_B64"'"1119 }1120 }1121 ]1122 }1123 }1124 ]1125 }1126 ]1127 }'11281129### Combine built-in tools and function calling11301131Gemini 3 allows the use of built-in tools (like Google Search, URL1132context, and [more](https://ai.google.dev/gemini-api/docs/tools)) and custom [function calling](https://ai.google.dev/gemini-api/docs/function-calling) tools in the same API call, allowing for1133more complex workflows. Learn more on the [tool combinations](https://ai.google.dev/gemini-api/docs/tool-combination) page.11341135### Python11361137 from google import genai1138 from google.genai import types11391140 client = genai.Client()11411142 getWeather = {1143 "name": "getWeather",1144 "description": "Gets the weather for a requested city.",1145 "parameters": {1146 "type": "object",1147 "properties": {1148 "city": {1149 "type": "string",1150 "description": "The city and state, e.g. Utqiaġvik, Alaska",1151 },1152 },1153 "required": ["city"],1154 },1155 }11561157 response = client.models.generate_content(1158 model="gemini-3-flash-preview",1159 contents="What is the northernmost city in the United States? What's the weather like there today?",1160 config=types.GenerateContentConfig(1161 tools=[1162 types.Tool(1163 google_search=types.ToolGoogleSearch(), # Built-in tool1164 function_declarations=[getWeather] # Custom tool1165 ),1166 ],1167 include_server_side_tool_invocations=True1168 ),1169 )11701171 history = [1172 types.Content(1173 role="user",1174 parts=[types.Part(text="What is the northernmost city in the United States? What's the weather like there today?")]1175 ),1176 response.candidates[0].content,1177 types.Content(1178 role="user",1179 parts=[types.Part(1180 function_response=types.FunctionResponse(1181 name="getWeather",1182 response={"response": "Very cold. 22 degrees Fahrenheit."},1183 id=response.candidates[0].content.parts[2].function_call.id1184 )1185 )]1186 )1187 ]11881189 response_2 = client.models.generate_content(1190 model="gemini-3-flash-preview",1191 contents=history,1192 config=types.GenerateContentConfig(1193 tools=[1194 types.Tool(1195 google_search=types.ToolGoogleSearch(),1196 function_declarations=[getWeather]1197 ),1198 ],1199 include_server_side_tool_invocations=True1200 ),1201 )12021203### Javascript12041205 import { GoogleGenAI } from '@google/genai';12061207 const client = new GoogleGenAI({});12081209 const getWeather = {1210 name: "getWeather",1211 description: "Get the weather in a given location",1212 parameters: {1213 type: "OBJECT",1214 properties: {1215 location: {1216 type: "STRING",1217 description: "The city and state, e.g. San Francisco, CA"1218 }1219 },1220 required: ["location"]1221 }1222 };12231224 async function run() {1225 const tools = [1226 { googleSearch: {} },1227 { functionDeclarations: [getWeather] }1228 ];1229 const toolConfig = { includeServerSideToolInvocations: true };12301231 const response1 = await client.models.generateContent({1232 model: "gemini-3-flash-preview",1233 contents: [{role: "user", parts: [{text: "What is the northernmost city in the United States? What's the weather like there today?"}]}],1234 config: {1235 tools: tools,1236 toolConfig: toolConfig,1237 },1238 });12391240 const functionCallId = response1.candidates[0].content.parts.find(p => p.functionCall)?.functionCall?.id;12411242 const history = [1243 {1244 role: "user",1245 parts:[{text: "What is the northernmost city in the United States? What's the weather like there today?"}]1246 },1247 response1.candidates[0].content,1248 {1249 role: "user",1250 parts: [{1251 functionResponse: {1252 name: "getWeather",1253 response: {response: "Very cold. 22 degrees Fahrenheit."},1254 id: functionCallId1255 }1256 }]1257 }1258 ];12591260 const response2 = await client.models.generateContent({1261 model: "gemini-3-flash-preview",1262 contents: history,1263 config: {1264 tools: tools,1265 toolConfig: toolConfig,1266 },1267 });1268 }12691270 run();12711272## Migrating from Gemini 2.512731274Gemini 3 is our most capable model family to date and offers a stepwise1275improvement over Gemini 2.5. When migrating, consider the following:12761277- **Thinking:** If you were previously using complex prompt engineering (like chain of thought) to force Gemini 2.5 to reason, try Gemini 3 with `thinking_level: "high"` and simplified prompts.1278- **Temperature settings:** If your existing code explicitly sets temperature (especially to low values for deterministic outputs), we recommend removing this parameter and using the Gemini 3 default of 1.0 to avoid potential looping issues or performance degradation on complex tasks.1279- **PDF \& document understanding:** If you relied on specific behavior for dense document parsing, test the new `media_resolution_high` setting to ensure continued accuracy.1280- **Token consumption:** Migrating to Gemini 3 defaults may **increase** token usage for PDFs but **decrease** token usage for video. If requests now exceed the context window due to higher default resolutions, we recommend explicitly reducing the media resolution.1281- **Image segmentation:** Image segmentation capabilities (returning pixel-level masks for objects) are not supported in Gemini 3 Pro or Gemini 3 Flash. For workloads requiring native image segmentation, we recommend continuing to utilize Gemini 2.5 Flash with thinking turned off.1282- **Computer Use:** Gemini 3 Pro and Gemini 3 Flash support [Computer1283 Use](https://ai.google.dev/gemini-api/docs/computer-use). Unlike the 2.5 series, you don't need to use a separate model to access the Computer Use tool.1284- **Tool support** : [Combining built-in tools with function calling](https://ai.google.dev/gemini-api/docs/tool-combination) is now supported for Gemini 3 models. [Maps1285 grounding](https://ai.google.dev/gemini-api/docs/maps-grounding) is also now supported for Gemini 3 models.1286- **Candidate count** : Gemini 3 models do not support `candidateCount > 1`. Setting this parameter to a value greater than `1` will return a 400 error.12871288## OpenAI compatibility12891290For users utilizing the [OpenAI compatibility layer](https://ai.google.dev/gemini-api/docs/openai),1291standard parameters (OpenAI's `reasoning_effort`) are automatically mapped to1292Gemini (`thinking_level`) equivalents.12931294## Prompting best practices12951296Gemini 3 is a reasoning model, which changes how you should prompt.12971298- **Precise instructions:** Be concise in your input prompts. Gemini 3 responds best to direct, clear instructions. It may over-analyze verbose or overly complex prompt engineering techniques used for older models.1299- **Output verbosity:** By default, Gemini 3 is less verbose and prefers providing direct, efficient answers. If your use case requires a more conversational or "chatty" persona, you must explicitly steer the model in the prompt (e.g., "Explain this as a friendly, talkative assistant").1300- **Context management:** When working with large datasets (e.g., entire books, codebases, or long videos), place your specific instructions or questions at the end of the prompt, after the data context. Anchor the model's reasoning to the provided data by starting your question with a phrase like, "Based on the information above...".13011302Learn more about prompt design strategies in the [prompt engineering guide](https://ai.google.dev/gemini-api/docs/prompting-strategies).13031304## FAQ130513061. **What is the knowledge cutoff for Gemini 3?** Gemini 3 models have a1307 knowledge cutoff of January 2025. For more recent information, use the1308 [Search Grounding](https://ai.google.dev/gemini-api/docs/google-search) tool.130913102. **What are the context window limits?** Gemini 3 models support a 1 million1311 token input context window and up to 64k tokens of output.131213133. **Is there a free tier for Gemini 3?** Gemini 3 Flash1314 `gemini-3-flash-preview` and 3.1 Flash-Lite `gemini-3.1-flash-lite` have1315 free tiers in the Gemini API. You can try Gemini 3.1 Pro and 3 Flash for free in1316 Google AI Studio, but there is no free tier available for1317 `gemini-3.1-pro-preview` in the Gemini API.131813194. **Will my old `thinking_budget` code still work?** Yes, `thinking_budget` is1320 still supported for backward compatibility, but we recommend migrating to1321 `thinking_level` for more predictable performance. Do not use both in the same1322 request.132313245. **Does Gemini 3 support the Batch API?** Yes, Gemini 3 supports the1325 [Batch API](https://ai.google.dev/gemini-api/docs/batch-api).132613276. **Is Context Caching supported?** Yes, [Context Caching](https://ai.google.dev/gemini-api/docs/caching) is supported for Gemini 3.132813297. **Which tools are supported in Gemini 3?** Gemini 3 supports [Google Search](https://ai.google.dev/gemini-api/docs/google-search), [Grounding with Google Maps](https://ai.google.dev/gemini-api/docs/maps-grounding), [File Search](https://ai.google.dev/gemini-api/docs/file-search),1330 [Code Execution](https://ai.google.dev/gemini-api/docs/code-execution), and [URL Context](https://ai.google.dev/gemini-api/docs/url-context). It also supports standard [Function Calling](https://ai.google.dev/gemini-api/docs/function-calling) for your own custom tools,1331 and in [combination with built-in tools](https://ai.google.dev/gemini-api/docs/tool-combination).133213338. **What is `gemini-3.1-pro-preview-customtools`?** If you are using `gemini-3.1-pro-preview` and the model ignores your custom tools in favor of bash commands, try the `gemini-3.1-pro-preview-customtools` model instead. More info [here](https://ai.google.dev/gemini-api/docs/models/gemini-3.1-pro-preview#gemini-31-pro-preview-customtools).13341335## Next steps13361337- Get started with the [Gemini 3 Cookbook](https://colab.research.google.com/github/google-gemini/cookbook/blob/main/quickstarts/Get_started.ipynb#templateParams=%7B%22MODEL_ID%22%3A+%22gemini-3-pro-preview%22%7D)1338- Check the dedicated Cookbook guide on [thinking levels](https://colab.research.google.com/github/google-gemini/cookbook/blob/main/quickstarts/Get_started_thinking_REST.ipynb#gemini3) and how to migrate from thinking budget to thinking levels.