Repository Public
1The Gemini Live API enables real-time, bidirectional voice conversations with2Gemini models.34Standard voice models work well for immediate back-and-forth dialogue. You speak5to the model, and it generates a spoken reply right away. But when a request6requires planning, complex analysis, or external tools, direct responses hit a7limit. The model must either answer without reasoning or pause silently while8waiting for tools to finish.910Thinking in the Live API (`gemini-3.8-live-extended-thinking`) adds background11reasoning to real-time voice sessions. The model plans and calls asynchronous12tools in the background while speaking natural conversational fillers to keep13the interaction active.1415This architecture changes the conversational lifecycle in two key ways:1617- **Conversational fillers**: The model speaks intermediate updates (such as "Checking flight options now") while executing tools in the background.18- **Interaction status tracking** : Because the model can speak multiple times during a single request, the server emits `interaction_status: "IN_PROGRESS"` during background processing and `interaction_status: "IDLE"` when the overall task completes.1920The following diagram compares the interaction lifecycles between standard Live21voice sessions and Thinking with background reasoning:22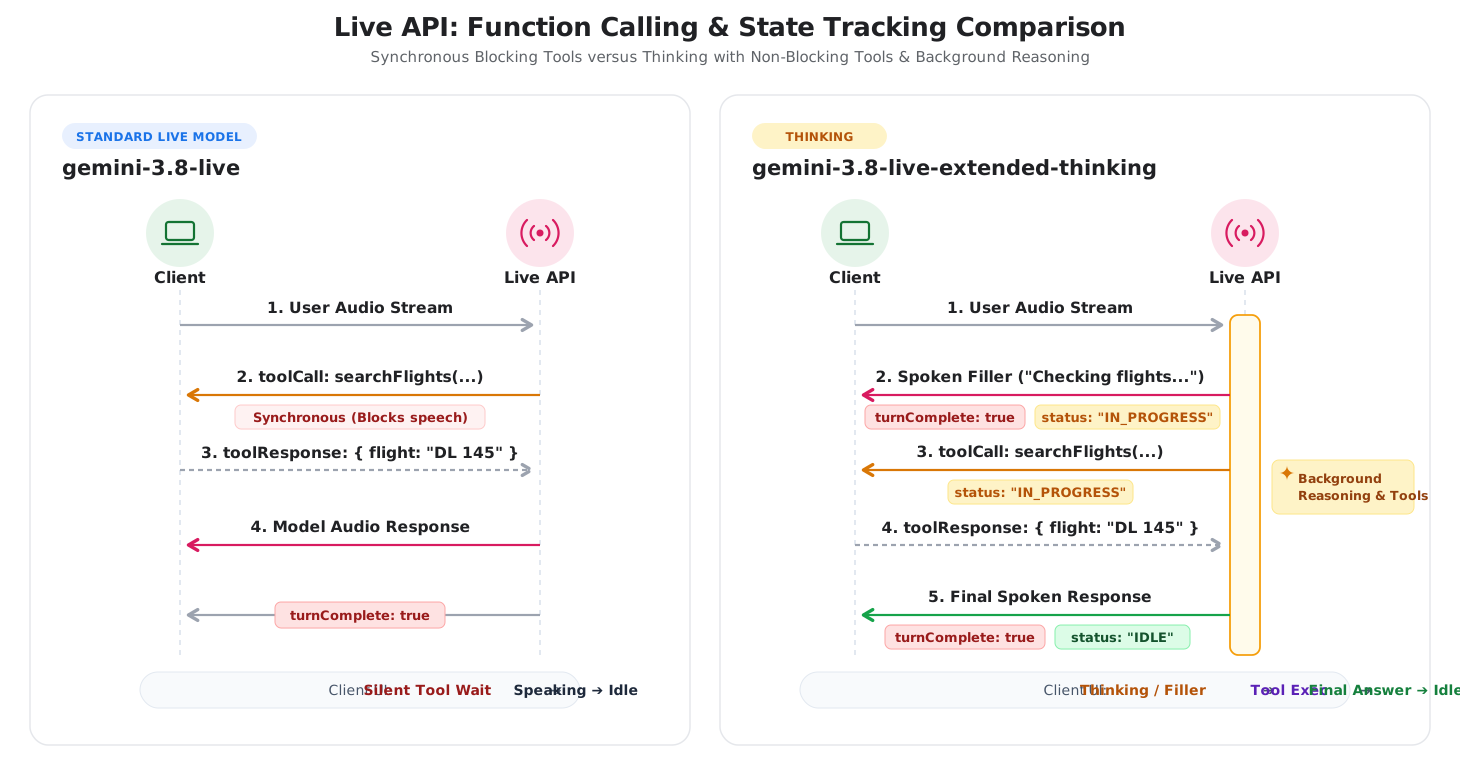2324## Choosing the right model2526When deciding between `gemini-3.8-live` and `gemini-3.8-live-extended-thinking`,27weigh three main considerations: response latency, task complexity, and client28state handling.2930### When to use Gemini 3.8 Live3132Use `gemini-3.8-live` for low-latency conversational voice agents where33immediate turn-taking is essential and tasks are direct.3435- **Conversational voice assistants**: Customer service triage, language practice, voice search, and interactive storytelling.36- **Fast tool execution**: Workflows where external tools return within milliseconds (such as reading sensor values or controlling smart devices).37- **Simple client logic** : Applications where each user turn receives a single model response, and `turnComplete: true` reliably signals when the session is idle.3839### When to use Gemini 3.8 Live Extended Thinking4041Use `gemini-3.8-live-extended-thinking` when your agent must evaluate complex42data, plan multiple steps, or handle tools that take several seconds to run.4344- **Multi-step diagnostics and support**: Technical support agents diagnosing system issues across multiple logs, error codes, and configuration checks.45- **Coordinated data retrieval**: Travel and booking agents that search flights, query hotels, and compare prices across parallel API calls.46- **STEM and code tutoring**: Educational agents that verify formulas, debug code, or work through multi-step logic before speaking an explanation.47- **Masking tool latency**: Voice experiences where long-running functions would otherwise create awkward silence for the listener.4849### Key differences summary5051The following table summarizes the technical differences between both models:5253| Feature | Gemini 3.8 Live | Gemini 3.8 Live Extended Thinking |54|---|---|---|55| **Primary use cases** | Low-latency voice agents, direct commands, fast tools | Multi-step problem solving, complex planning, multi-tool workflows |56| **Model endpoint** | `gemini-3.8-live` | `gemini-3.8-live-extended-thinking` |57| **Reasoning architecture** | Interleaved reasoning with fixed latency profile (`thinking_level` not supported) | Configurable background reasoning (`thinking_level`: `low`, `medium`, `high`; `MINIMAL` not supported) |58| **Turn boundaries** | `turnComplete: true` closes the turn and returns to idle | `turnComplete: true` finishes an utterance; `interaction_status` controls session lifecycle |59| **Conversational fillers** | Model waits for tool execution before speaking | Model streams intermediate conversational fillers while processing |60| **Tool execution** | Supports synchronous (`BLOCKING`) and asynchronous (`NON_BLOCKING`) tools | Requires asynchronous (`NON_BLOCKING`) tool declarations |6162## Migration and integration paths6364Follow these steps to upgrade existing voice applications or integrate Thinking65into your Live API sessions.6667### Upgrading from Gemini 3.1 Flash Live6869For existing voice applications using `gemini-3.1-flash-live-preview`, upgrading70to `gemini-3.8-live` requires updating the model string and omitting71`thinking_level` (or `thinking_config`) from your setup configuration, as72`thinking_level` is not supported for `gemini-3.8-live`:7374 {75 "setup": {76 "model": "models/gemini-3.8-live"77 }78 }7980The turn lifecycle and `turnComplete` signals remain identical.8182### Adopting Thinking8384To adopt `gemini-3.8-live-extended-thinking`, update three integration points:85861. **Track `interaction_status` instead of `turnComplete`** : In Thinking87 sessions, the model can emit intermediate conversational fillers while88 reasoning. Inspect the `interaction_status` field on incoming server messages89 to manage UI state. Only return to idle when `interaction_status` is `IDLE`.9091 ### Python9293 status = getattr(message, "interaction_status", None)94 if status == "IDLE":95 # Ready for user input96 set_ui_state("listening")97 elif status == "IN_PROGRESS":98 # Reasoning or executing tools99 set_ui_state("thinking")100101 ### JavaScript102103 if (message.interactionStatus === 'IDLE') {104 // Ready for user input105 setUiState('listening');106 } else if (message.interactionStatus === 'IN_PROGRESS') {107 // Reasoning or executing tools108 setUiState('thinking');109 }1101112. **Declare non-blocking functions** : Set `"behavior": "NON_BLOCKING"` on all112 function declarations. Thinking models run tools asynchronously in the113 background while streaming verbal updates. Synchronous blocking tools return114 an error.115116 ### Python117118 search_flights = types.FunctionDeclaration(119 name="search_flights",120 description="Searches for available flights.",121 behavior="NON_BLOCKING",122 parameters={123 "type": "OBJECT",124 "properties": {125 "destination": {"type": "STRING"},126 },127 "required": ["destination"],128 },129 )130131 ### JavaScript132133 const searchFlights = {134 name: 'search_flights',135 description: 'Searches for available flights.',136 behavior: 'NON_BLOCKING',137 parameters: {138 type: 'OBJECT',139 properties: {140 destination: { type: 'STRING' },141 },142 required: ['destination'],143 },144 };1451463. **Configure reasoning depth** : Set `thinking_config` in your session147 configuration to adjust reasoning levels (`low`, `medium`, or `high`;148 `MINIMAL` is not supported).149150 ### Python151152 config = types.LiveConnectConfig(153 response_modalities=["AUDIO"],154 thinking_config=types.ThinkingConfig(155 thinking_level="low",156 ),157 tools=[types.Tool(function_declarations=[search_flights])],158 )159160 ### JavaScript161162 const config = {163 responseModalities: [Modality.AUDIO],164 thinkingConfig: {165 thinkingLevel: 'low',166 },167 tools: [{ functionDeclarations: [searchFlights] }],168 };169170## Protocol side-by-side comparison171172This section compares the WebSocket messages exchanged during each phase of a173Live API session.174175### Step 1: Session setup176177Both models connect to the same WebSocket endpoint:178179 wss://generativelanguage.googleapis.com/ws/google.ai.generativelanguage.v1alpha.GenerativeService.BidiGenerateContent?key=$API_KEY180181- **Identical**: WebSocket URL and API key authentication.182- **Model string** : `gemini-3.8-live` versus `gemini-3.8-live-extended-thinking`.183- **Thinking configuration** : Thinking adds `thinkingConfig` to adjust reasoning depth.184- **Tool behavior** : Thinking requires `"behavior": "NON_BLOCKING"` on185 function declarations.186187### Gemini 3.8 Live188189 {190 "setup": {191 "model": "models/gemini-3.8-live",192 "generationConfig": {193 "responseModalities": ["AUDIO"],194 "speechConfig": {195 "voiceConfig": {196 "prebuiltVoiceConfig": {197 "voiceName": "Puck"198 }199 }200 }201 }202 }203 }204205### Gemini 3.8 Live Extended Thinking206207 {208 "setup": {209 "model": "models/gemini-3.8-live-extended-thinking",210 "generationConfig": {211 "responseModalities": ["AUDIO"],212 "speechConfig": {213 "voiceConfig": {214 "prebuiltVoiceConfig": {215 "voiceName": "Puck"216 }217 }218 },219 "thinkingConfig": {220 "thinkingLevel": "LOW"221 }222 },223 "tools": [{224 "functionDeclarations": [{225 "name": "searchFlights",226 "description": "Searches for flights between cities.",227 "behavior": "NON_BLOCKING",228 "parameters": {229 "type": "OBJECT",230 "properties": {231 "destination": { "type": "STRING" }232 },233 "required": ["destination"]234 }235 }]236 }]237 }238 }239240Both models receive the same server acknowledgment upon connection:241242 {243 "setupComplete": {}244 }245246### Step 2: User audio input247248Audio streaming is identical across both models. Real-time 16kHz raw PCM audio249chunks are streamed using `realtimeInput`:250251 {252 "realtimeInput": {253 "audio": {254 "data": "UklGRiQAAABXQVZF...",255 "mimeType": "audio/pcm;rate=16000"256 }257 }258 }259260### Step 3: Model response and state lifecycle261262Both models stream 24kHz PCM audio chunks in `serverContent.modelTurn`. However,263lifecycle management differs:264265#### Gemini 3.8 Live response flow2662671. The server streams audio chunks for the turn.2682. The server sends `turnComplete: true`, indicating the model is finished speaking and the session is idle.269270 // 1. Audio stream chunks271 {272 "serverContent": {273 "modelTurn": {274 "parts": [275 {276 "inlineData": {277 "mimeType": "audio/pcm;rate=24000",278 "data": "..."279 }280 }281 ]282 }283 }284 }285286 // 2. Turn completion -> Signals client to switch UI to Idle/Listening287 {288 "serverContent": {289 "turnComplete": true290 }291 }292293#### Gemini 3.8 Live Extended Thinking response flow2942951. **Spoken filler** : The model emits intermediate speech (such as *"Checking flights to Seattle..."* ) with `turnComplete: true` and `interactionStatus: "IN_PROGRESS"`.2962. **Asynchronous tool call** : The server emits the tool call while `interactionStatus` remains `"IN_PROGRESS"`, indicating that the server is actively processing the multi-step turn and waiting for the tool response.2973. **Tool response**: The client executes the function and returns the output.2984. **Final response** : The server delivers the complete answer with `turnComplete: true` and `interactionStatus: "IDLE"`.299300 // 1. Spoken verbal filler while background reasoning proceeds301 {302 "serverContent": {303 "modelTurn": {304 "parts": [305 {306 "inlineData": {307 "mimeType": "audio/pcm;rate=24000",308 "data": "..."309 }310 }311 ]312 },313 "turnComplete": true,314 "interactionStatus": "IN_PROGRESS"315 }316 }317318 // 2. Asynchronous tool call emitted with IN_PROGRESS status319 {320 "toolCall": {321 "functionCalls": [322 {323 "id": "call_123",324 "name": "searchFlights",325 "args": {326 "destination": "Seattle"327 }328 }329 ]330 },331 "interactionStatus": "IN_PROGRESS"332 }333334 // 3. Client executes function and returns result335 {336 "toolResponse": {337 "functionResponses": [338 {339 "response": {340 "output": {341 "flight": "DL 145",342 "price": "$145"343 }344 },345 "id": "call_123"346 }347 ]348 }349 }350351 // 4. Final spoken answer delivered -> session transitions to IDLE when done352 {353 "serverContent": {354 "modelTurn": {355 "parts": [356 {357 "inlineData": {358 "mimeType": "audio/pcm;rate=24000",359 "data": "..."360 }361 }362 ]363 },364 "interactionStatus": "IDLE",365 "turnComplete": true366 }367 }368369## SDK implementation examples370371The following examples show how to configure Thinking and handle372`interaction_status` using the Google GenAI SDK.373374### Python375376 import asyncio377 from google import genai378 from google.genai import types379380 client = genai.Client()381 model = "gemini-3.8-live-extended-thinking"382383 # Define non-blocking function declaration384 search_flights = types.FunctionDeclaration(385 name="search_flights",386 description="Searches for available flights to a destination.",387 behavior="NON_BLOCKING",388 parameters={389 "type": "OBJECT",390 "properties": {391 "destination": {"type": "STRING"}392 },393 "required": ["destination"]394 }395 )396397 config = types.LiveConnectConfig(398 response_modalities=["AUDIO"],399 thinking_config=types.ThinkingConfig(400 thinking_level="low"401 ),402 tools=[types.Tool(function_declarations=[search_flights])]403 )404405 async def main():406 async with client.aio.live.connect(model=model, config=config) as session:407 print("Session connected with Thinking")408409 async for message in session.receive():410 # Inspect interaction status for server lifecycle tracking411 status = getattr(message, "interaction_status", None)412 if status:413 print(f"Interaction status: {status}")414415 # Handle audio output parts416 if message.server_content and message.server_content.model_turn:417 for part in message.server_content.model_turn.parts:418 if part.inline_data:419 # Process 24kHz audio chunk420 pass421422 # Handle asynchronous tool call423 if message.tool_call:424 for call in message.tool_call.function_calls:425 print(f"Executing tool: {call.name}")426 # Simulate function execution427 response = types.FunctionResponse(428 id=call.id,429 name=call.name,430 response={"result": "Flight DL 145 ($145)"}431 )432 await session.send_tool_response(433 function_responses=[response]434 )435436 # Status is IDLE when reasoning and all turns are complete437 if status == "IDLE":438 print("Session is idle and ready for user input.")439440 if __name__ == "__main__":441 asyncio.run(main())442443### JavaScript444445 import { GoogleGenAI, Modality } from '@google/genai';446447 const ai = new GoogleGenAI({});448 const model = 'gemini-3.8-live-extended-thinking';449450 const searchFlights = {451 name: 'search_flights',452 description: 'Searches for available flights to a destination.',453 behavior: 'NON_BLOCKING',454 parameters: {455 type: 'OBJECT',456 properties: {457 destination: { type: 'STRING' }458 },459 required: ['destination']460 }461 };462463 const config = {464 responseModalities: [Modality.AUDIO],465 thinkingConfig: {466 thinkingLevel: 'low'467 },468 tools: [{ functionDeclarations: [searchFlights] }]469 };470471 async function main() {472 const session = await ai.live.connect({473 model: model,474 config: config,475 callbacks: {476 onopen: () => console.log('Session connected'),477 onmessage: async (event) => {478 const message = JSON.parse(event.data);479480 if (message.interactionStatus) {481 console.log(`Interaction status: ${message.interactionStatus}`);482 }483484 if (message.toolCall) {485 for (const call of message.toolCall.functionCalls) {486 console.log(`Executing tool: ${call.name}`);487 session.sendToolResponse({488 functionResponses: [{489 id: call.id,490 name: call.name,491 response: { result: 'Flight DL 145 ($145)' }492 }]493 });494 }495 }496497 if (message.interactionStatus === 'IDLE') {498 console.log('Session is idle and waiting for input.');499 }500 }501 }502 });503 }504505 main();506507## What's next508509- Read the [Gemini 3.8 Live](https://ai.google.dev/gemini-api/docs/models/gemini-3.8-live) and [Gemini 3.8 Live Extended Thinking](https://ai.google.dev/gemini-api/docs/models/gemini-3.8-live-extended-thinking) model pages.510- Check the [Model comparison](https://ai.google.dev/gemini-api/docs/live-api/capabilities#model-comparison) table for detailed feature comparisons across all Live API models.511- Learn more about function calling in the [Live API Tool use](https://ai.google.dev/gemini-api/docs/live-api/tools) guide.512- Review [Session management](https://ai.google.dev/gemini-api/docs/live-api/session-management) to handle session resumption and context lifecycle.