Gemini Robotics ER models can point to objects, track them in video, detect them with bounding boxes, and generate movement trajectories.
For full runnable code, see the Robotics cookbook.
Point to objects
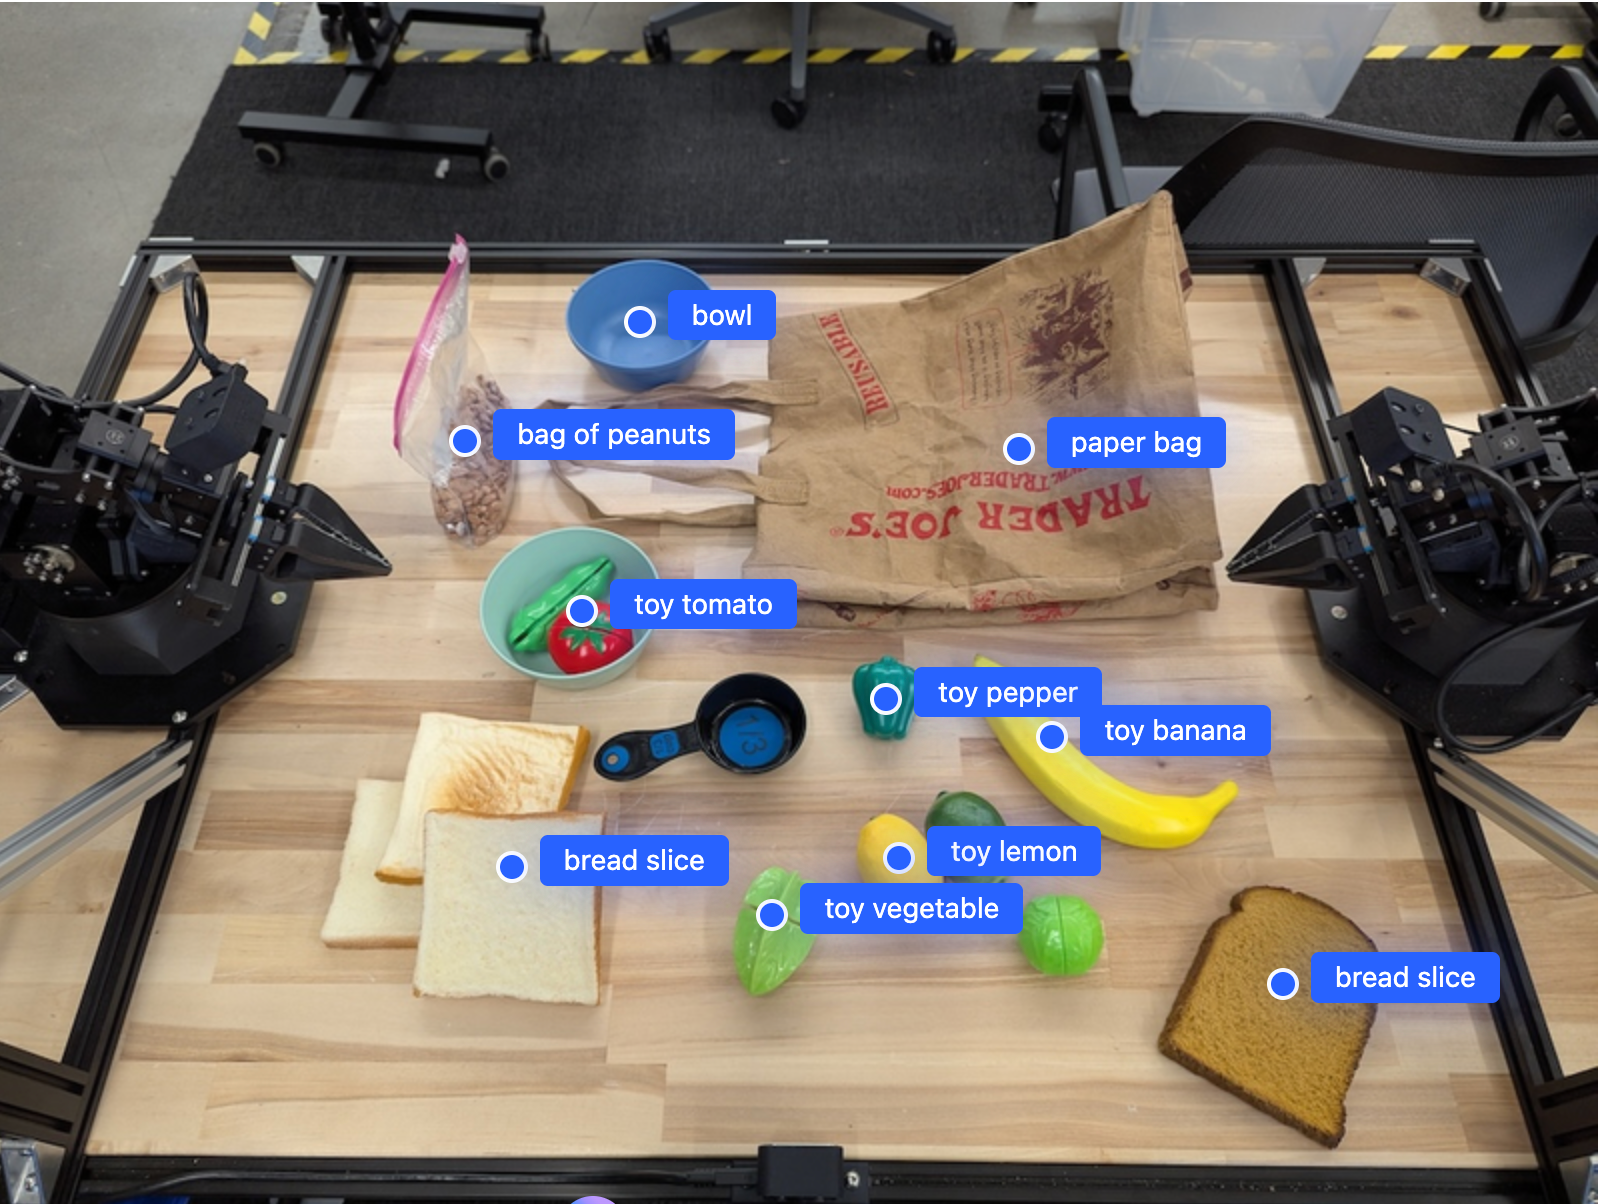
The following example finds specific objects in an image and returns their
normalized [y, x] coordinates:
Python
from google import genai

PROMPT = """
          Point to no more than 10 items in the image. The label returned
          should be an identifying name for the object detected.
          The answer should follow the json format: [{"point": <point>,
          "label": <label1>}, ...]. The points are in [y, x] format
          normalized to 0-1000.
        """
client = genai.Client()

uploaded_file = client.files.upload(file="my-image.png")

image_response = client.interactions.create(
    model="gemini-robotics-er-2-preview",
    input=[
        {
            "type": "image",
            "uri": uploaded_file.uri,
            "mime_type": uploaded_file.mime_type
        },
        {"type": "text", "text": PROMPT}
    ],
    generation_config={"thinking_level": "high"},
)

print(image_response.output_text)
REST
# First, ensure you have the image file locally.
# Encode the image to base64
IMAGE_BASE64=$(base64 -w 0 my-image.png)

curl -X POST \
  "https://generativelanguage.googleapis.com/v1beta/interactions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gemini-robotics-er-2-preview",
    "input": {
      "parts": [
        {
          "inlineData": {
            "mimeType": "image/png",
            "data": "'"${IMAGE_BASE64}"'"
          }
        },
        {
          "text": "Point to no more than 10 items in the image. The label returned should be an identifying name for the object detected. The answer should follow the json format: [{\"point\": [y, x], \"label\": <label1>}, ...]. The points are in [y, x] format normalized to 0-1000."
        }
      ]
    },
    "generation_config": {
      "thinking_config": {
        "thinking_level": "high"
      }
    }
  }'
The output will be a JSON array containing objects, each with a point
(normalized [y, x] coordinates) and a label identifying the object.
JSON
[
  {"point": [376, 508], "label": "small banana"},
  {"point": [287, 609], "label": "larger banana"},
  {"point": [223, 303], "label": "pink starfruit"},
  {"point": [435, 172], "label": "paper bag"},
  {"point": [270, 786], "label": "green plastic bowl"},
  {"point": [488, 775], "label": "metal measuring cup"},
  {"point": [673, 580], "label": "dark blue bowl"},
  {"point": [471, 353], "label": "light blue bowl"},
  {"point": [492, 497], "label": "bread"},
  {"point": [525, 429], "label": "lime"}
]
The following image is an example of how these points can be displayed:
Tracking objects in a video
Gemini Robotics ER 2 can also analyze video frames to track objects over time. See Video inputs for a list of supported video formats.
Python
from google import genai

client = genai.Client()

uploaded_file = client.files.upload(file="my-video.mp4")

prompt = """
          Point to the red ball in every frame where it appears.
          The answer should follow the json format: [{"point": [y, x],
          "label": <label>}, ...]. The points are in [y, x] format
          normalized to 0-1000. Return one entry per frame that contains
          the object.
        """

image_response = client.interactions.create(
  model="gemini-robotics-er-2-preview",
  input=[
    {
        "type": "video",
        "uri": uploaded_file.uri,
        "mime_type": uploaded_file.mime_type
    },
    {"type": "text", "text": prompt}
  ],
)

print(image_response.output_text)
Object detection and bounding boxes
In addition to points, you can prompt the model to return 2D bounding boxes, which provide more spatial detail for detected objects.
Python
from google import genai

client = genai.Client()

uploaded_file = client.files.upload(file="my-image.png")

prompt = """
          Detect all objects in this image and return bounding boxes.
          The answer should follow the JSON format:
          [{"label": <label>, "y": <y_min>, "x": <x_min>,
            "y2": <y_max>, "x2": <x_max>}, ...]
          where coordinates are normalized to 0-1000.
        """

image_response = client.interactions.create(
  model="gemini-robotics-er-2-preview",
  input=[
    {
        "type": "image",
        "uri": uploaded_file.uri,
        "mime_type": uploaded_file.mime_type
    },
    {"type": "text", "text": prompt}
  ],
)

print(image_response.output_text)
Trajectories
Gemini Robotics ER 2 can generate sequences of points that define a trajectory, useful for guiding robot movement.
This example requests a trajectory to move a red pen to an organizer, including an estimate of the intermediate waypoints. The code has been reduced to show only the prompt.
Python
prompt = """
          Generate a trajectory for the robotic arm to pick up the red pen
          and place it in the organizer. Return a list of waypoints as JSON:
          [{"step": <int>, "point": [y, x], "action": <description>}, ...]
          where coordinates are normalized to 0-1000.
        """
Making room for a laptop
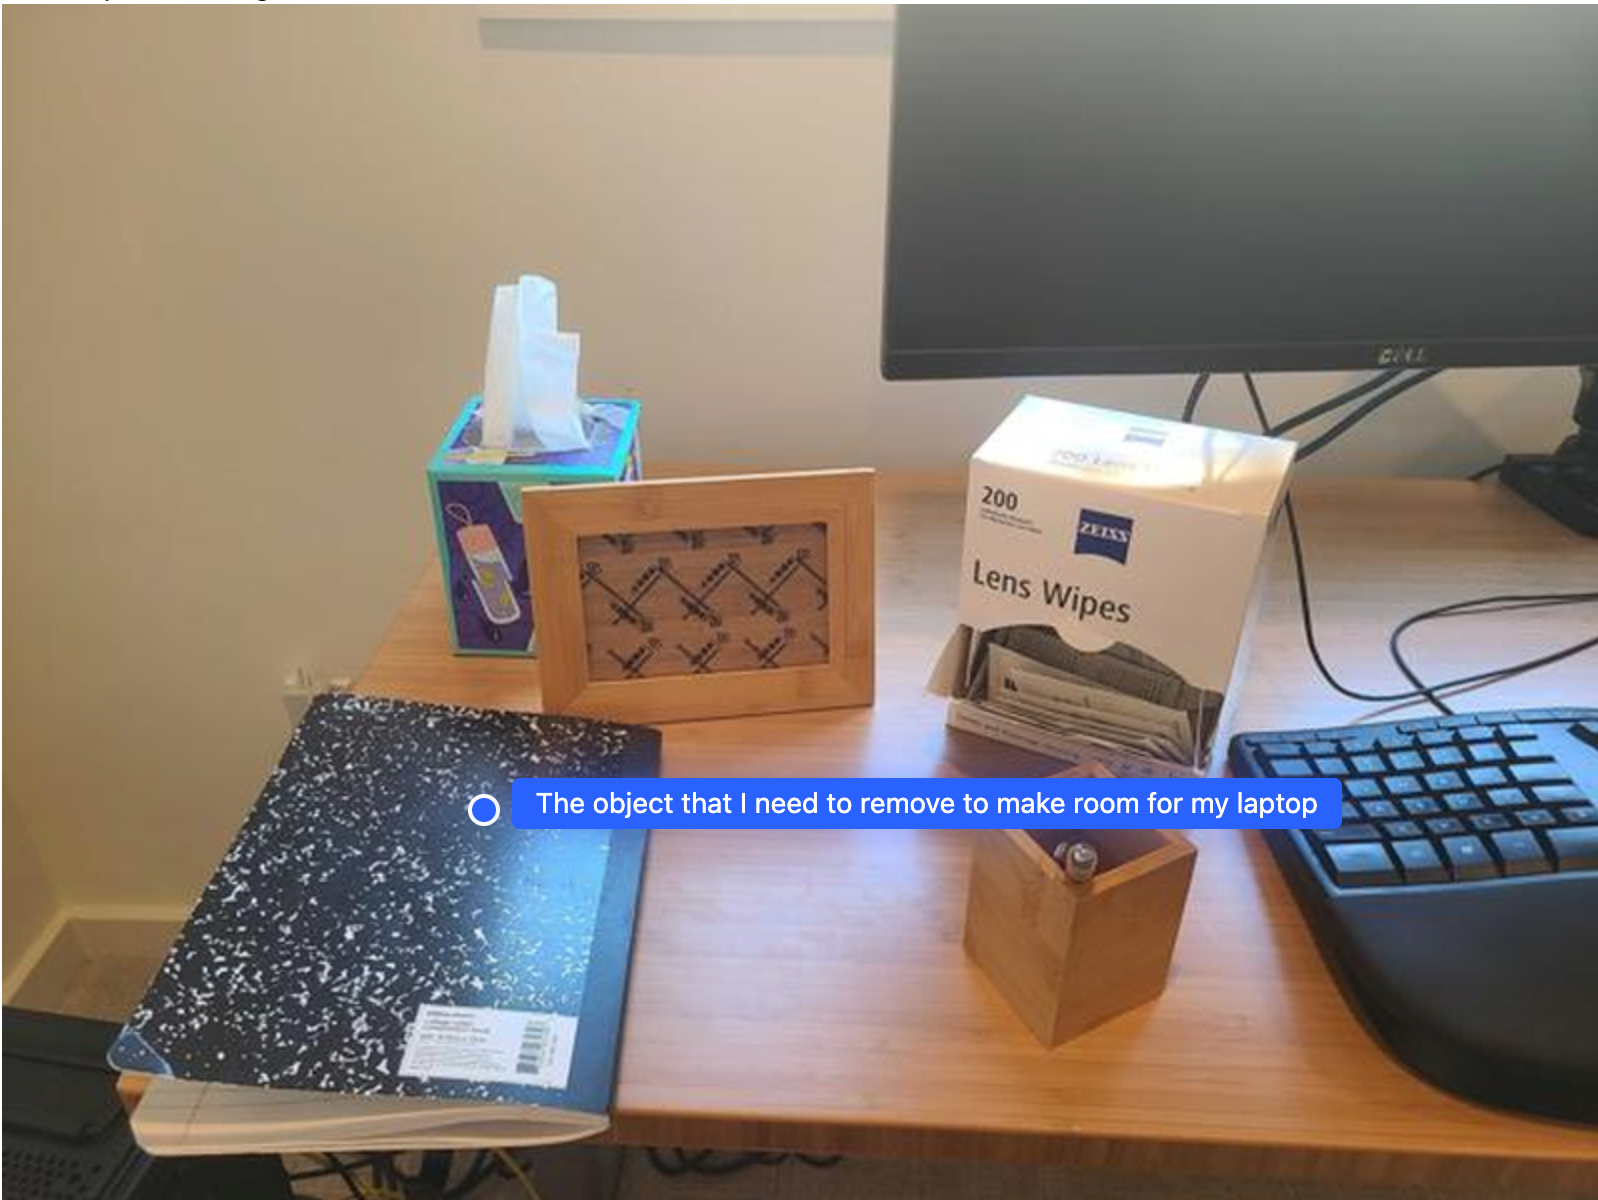
This example shows how Gemini Robotics ER can reason about a space. The prompt asks the model to identify which object needs to be moved to create space for another item.
Python
from google import genai

client = genai.Client()

uploaded_file = client.files.upload(file="path/to/image-with-objects.jpg")

prompt = """
          Point to the object that I need to remove to make room for my laptop
          The answer should follow the JSON format: [{"point": <point>,
          "label": <label1>}, ...]. The points are in [y, x] format normalized to 0-1000.
        """

image_response = client.interactions.create(
  model="gemini-robotics-er-2-preview",
  input=[
    {
        "type": "image",
        "uri": uploaded_file.uri,
        "mime_type": uploaded_file.mime_type
    },
    {"type": "text", "text": prompt}
  ],
)

print(image_response.output_text)
The response contains a 2D coordinate of the object that answers the user's question, in this case, the object that should move to make room for a laptop.
[
  {"point": [672, 301], "label": "The object that I need to remove to make room for my laptop"}
]
Packing a lunch
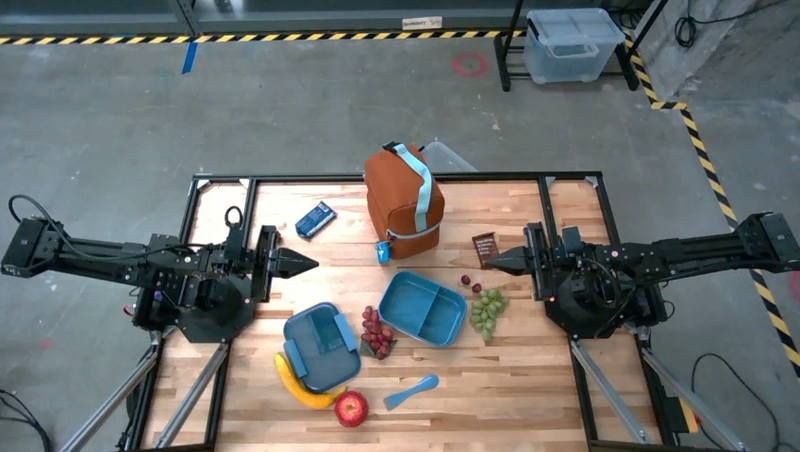
The model can also provide instructions for multi-step tasks and point to relevant objects for each step. This example shows how the model plans a series of steps to pack a lunch bag.
Python
from google import genai

client = genai.Client()

uploaded_file = client.files.upload(file="path/to/image-of-lunch.jpg")

prompt = """
          Explain how to pack the lunch box and lunch bag. Point to each
          object that you refer to. Each point should be in the format:
          [{"point": [y, x], "label": }], where the coordinates are
          normalized between 0-1000.
        """

image_response = client.interactions.create(
  model="gemini-robotics-er-2-preview",
  input=[
    {
        "type": "image",
        "uri": uploaded_file.uri,
        "mime_type": uploaded_file.mime_type
    },
    {"type": "text", "text": prompt}
  ],
)

print(image_response.output_text)
The response of this prompt is a set of step by step instructions on how to pack a lunch bag from the image input.
Input image
Model output
Based on the image, here is a plan to pack the lunch box and lunch bag:

1.  **Pack the fruit into the lunch box.** Place the [apple](apple), [banana](banana), [red grapes](red grapes), and [green grapes](green grapes) into the [blue lunch box](blue lunch box).
2.  **Add the spoon to the lunch box.** Put the [blue spoon](blue spoon) inside the lunch box as well.
3.  **Close the lunch box.** Secure the lid on the [blue lunch box](blue lunch box).
4.  **Place the lunch box inside the lunch bag.** Put the closed [blue lunch box](blue lunch box) into the [brown lunch bag](brown lunch bag).
5.  **Pack the remaining items into the lunch bag.** Place the [blue snack bar](blue snack bar) and the [brown snack bar](brown snack bar) into the [brown lunch bag](brown lunch bag).

Here is the list of objects and their locations:
*   [{"point": [899, 440], "label": "apple"}]
*   [{"point": [814, 363], "label": "banana"}]
*   [{"point": [727, 470], "label": "red grapes"}]
*   [{"point": [675, 608], "label": "green grapes"}]
*   [{"point": [706, 529], "label": "blue lunch box"}]
*   [{"point": [864, 517], "label": "blue spoon"}]
*   [{"point": [499, 401], "label": "blue snack bar"}]
*   [{"point": [614, 705], "label": "brown snack bar"}]
*   [{"point": [448, 501], "label": "brown lunch bag"}]
What's next
- Agentic capabilities --- code execution, instrument reading, image annotation.
- Task orchestration --- long-horizon tasks with custom robot APIs.
- Robotics with streaming --- real-time bidirectional streaming (Gemini Robotics ER 2 only).
- Video understanding --- moment finding and progress classification (Gemini Robotics ER 2 only).