Repository Public
1# Safety and factuality guidance23Generative artificial intelligence models are powerful tools, but they are not4without their limitations. Their versatility and applicability can sometimes5lead to unexpected outputs, such as outputs that are inaccurate, biased, or6offensive. Post-processing, and rigorous manual evaluation are essential to7limit the risk of harm from such outputs.89The models provided by the Gemini API can be used for a wide variety of10generative AI and natural language processing (NLP) applications. Use of these11functions is only available through the Gemini API or the Google AI Studio web12app. Your use of Gemini API is also subject to the [Generative AI Prohibited Use13Policy](https://policies.google.com/terms/generative-ai/use-policy) and the14[Gemini API terms of service](https://ai.google.dev/terms).1516Part of what makes large language models (LLMs) so useful is that they're17creative tools that can address many different language tasks. Unfortunately,18this also means that large language models can generate output that you don't19expect, including text that's offensive, insensitive, or factually incorrect.20What's more, the incredible versatility of these models is also what makes it difficult to21predict exactly what kinds of undesirable output they might produce. While the22Gemini API has been designed with [Google's AI23principles](https://ai.google/principles/) in mind, the onus is on developers to24apply these models responsibly. To aid developers in creating safe, responsible25applications, the Gemini API has some built-in content filtering as well as26adjustable safety settings across 4 dimensions of harm. Refer to the27[safety settings](https://ai.google.dev/gemini-api/docs/safety-settings) guide to learn more. It also offers Grounding28with Google Search enabled to improve factuality, though this may be disabled29for developers whose use cases are more creative and not information-seeking.3031This document is meant to introduce you to some safety risks that can arise when32using LLMs, and recommend emerging safety design and development33recommendations. (Note that laws and regulations may also impose restrictions,34but such considerations are beyond the scope of this guide.)3536The following steps are recommended when building applications with LLMs:3738- Understanding the safety risks of your application39- Considering adjustments to mitigate safety risks40- Performing safety testing appropriate to your use case41- Soliciting feedback from users and monitoring usage4243The adjustment and testing phases should be iterative until you reach44performance appropriate for your application.4546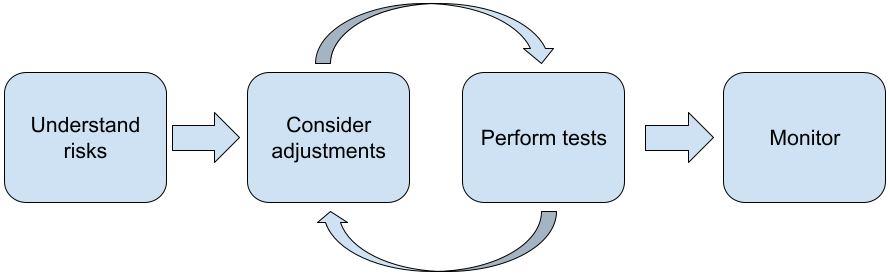4748## Understand the safety risks of your application4950In this context, safety is being defined as the ability of an LLM to avoid51causing harm to its users, for example, by generating toxic language or content52that promotes stereotypes. The models available through the Gemini API have been53designed with [Google's AI principles](https://ai.google/principles/) in mind54and your use of it is subject to the [Generative AI Prohibited Use55Policy](https://policies.google.com/terms/generative-ai/use-policy). The API56provides built-in safety filters to help address some common language model57problems such as toxic language and hate speech, and striving for inclusiveness58and avoidance of stereotypes. However, each application can pose a different set59of risks to its users. So as the application owner, you are responsible for60knowing your users and the potential harms your application may cause, and61ensuring that your application uses LLMs safely and responsibly.6263As part of this assessment, you should consider the likelihood that harm could64occur and determine its seriousness and mitigation steps. For example, an65app that generates essays based on factual events would need to be more careful66about avoiding misinformation, as compared to an app that generates fictional67stories for entertainment. A good way to begin exploring potential safety risks68is to research your end users, and others who might be affected by your69application's results. This can take many forms including researching state of70the art studies in your app domain, observing how people are using similar apps,71or running a user study, survey, or conducting informal interviews with72potential users.7374### Advanced tips7576- Speak with a diverse mix of prospective users within your target population about your application and its intended purpose so as to get a wider perspective on potential risks and to adjust diversity criteria as needed.77- The [AI Risk Management Framework](https://www.nist.gov/itl/ai-risk-management-framework) released by the U.S. government's National Institute of Standards and Technology (NIST) provides more detailed guidance and additional learning resources for AI risk management.78- DeepMind's publication on the [ethical and social risks of harm from language models](https://arxiv.org/abs/2112.04359) describes in detail the ways that language model applications can cause harm.7980## Consider adjustments to mitigate safety and factuality risks8182Now that you have an understanding of the risks, you can decide how to mitigate83them. Determining which risks to prioritize and how much you should do to try to84prevent them is a critical decision, similar to triaging bugs in a software85project. Once you've determined priorities, you can start thinking about the86types of mitigations that would be most appropriate. Often simple changes can87make a difference and reduce risks.8889For example, when designing an application consider:9091- **Tuning the model output** to better reflect what is acceptable in your application context. Tuning can make the output of the model more predictable and consistent and therefore can help mitigate certain risks.92- **Providing an input method that facilities safer outputs.** The exact input you give to an LLM can make a difference in the quality of the output. Experimenting with input prompts to find what works most safely in your use-case is well worth the effort, as you can then provide a UX that facilitates it. For example, you could restrict users to choose only from a drop-down list of input prompts, or offer pop-up suggestions with descriptive phrases which you've found perform safely in your application context.93- **Blocking unsafe inputs and filtering output before it is shown to the94 user.** In simple situations, blocklists can be used to identify and block95 unsafe words or phrases in prompts or responses, or require human reviewers96 to manually alter or block such content.9798 > [!NOTE]99 > **Note:** Automatically blocking based on a static list can have unintended results such as targeting a particular group that commonly uses vocabulary in the blocklist.100101- **Using trained classifiers to label each prompt with potential harms or102 adversarial signals.** Different strategies can then be employed on how to103 handle the request based on the type of harm detected. For example, If the104 input is overtly adversarial or abusive in nature, it could be blocked and105 instead output a pre-scripted response.106 **Advanced tip:** If signals determine the output to be harmful, the107 application can employ the following options:108109 - Provide an error message or pre-scripted output.110 - Try the prompt again, in case an alternative safe output is generated, since sometimes the same prompt will elicit different outputs.111- **Putting safeguards in place against deliberate misuse** such as assigning112 each user a unique ID and imposing a limit on the volume of user queries113 that can be submitted in a given period. Another safeguard is to try and114 protect against possible prompt injection. Prompt injection, much like SQL115 injection, is a way for malicious users to design an input prompt that116 manipulates the output of the model, for example, by sending an input prompt117 that instructs the model to ignore any previous examples. See the118 [Generative AI Prohibited Use Policy](https://policies.google.com/terms/generative-ai/use-policy)119 for details about deliberate misuse.120121- **Adjusting functionality to something that is inherently lower risk.**122 Tasks that are narrower in scope (e.g., extracting keywords from passages of123 text) or that have greater human oversight (e.g., generating short-form124 content that will be reviewed by a human), often pose a lower risk. So for125 instance, instead of creating an application to write an email reply from126 scratch, you might instead limit it to expanding on an outline or suggesting127 alternative phrasings.128129- **Adjusting harmful content safety settings to decrease how likely you are to130 see responses that could be harmful.** The Gemini API provides safety settings131 that you can adjust during the prototyping stage to determine if your132 application requires more or less restrictive safety configuration. You can133 adjust these settings across five filter categories to restrict or allow134 certain types of content. Refer to the [safety settings guide](https://ai.google.dev/gemini-api/docs/safety-settings) to learn about135 the adjustable safety settings available through the Gemini API.136137- **Decrease potential factual inaccuracies or hallucinations by enabling138 Grounding with Google Search**. Remember, many AI models are experimental139 and may present factually inaccurate information, hallucinate, or otherwise140 produce problematic outputs. The Grounding with Google Search feature connects141 the Gemini model to real-time web content and works with all available142 languages. This allows Gemini to provide more accurate answers and cite143 verifiable sources beyond the models knowledge cutoff.144145## Perform safety testing appropriate to your use case146147Testing is a key part of building robust and safe applications, but the extent,148scope and strategies for testing will vary. For example, a just-for-fun haiku149generator is likely to pose less severe risks than, say, an application designed150for use by law firms to summarize legal documents and help draft contracts. But151the haiku generator may be used by a wider variety of users which means the152potential for adversarial attempts or even unintended harmful inputs can be153greater. The implementation context also matters. For instance, an application154with outputs that are reviewed by human experts prior to any action being taken155might be deemed less likely to produce harmful outputs than the identical156application without such oversight.157158It's not uncommon to go through several iterations of making changes and testing159before feeling confident that you're ready to launch, even for applications that160are relatively low risk. Two kinds of testing are particularly useful for AI161applications:162163- **Safety benchmarking** involves designing safety metrics that reflect the164 ways your application could be unsafe in the context of how it is likely to165 get used, then testing how well your application performs on the metrics166 using evaluation datasets. It's good practice to think about the minimum167 acceptable levels of safety metrics before testing so that 1) you can168 evaluate the test results against those expectations and 2) you can gather169 the evaluation dataset based on the tests that evaluate the metrics you care170 about most.171172 **Advanced tips:**173 - Beware of over-relying on "off the shelf" approaches as it's likely you'll need to build your own testing datasets using human raters to fully suit your application's context.174 - If you have more than one metric you'll need to decide how you'll trade off if a change leads to improvements for one metric to the detriment of another. Like with other performance engineering, you may want to focus on worst-case performance across your evaluation set rather than average performance.175- **Adversarial testing** involves proactively trying to break your176 application. The goal is to identify points of weakness so that you can take177 steps to remedy them as appropriate. Adversarial testing can take178 significant time/effort from evaluators with expertise in your application ---179 but the more you do, the greater your chance of spotting problems,180 especially those occurring rarely or only after repeated runs of the181 application.182183 - Adversarial testing is a method for systematically evaluating an ML model with the intent of learning how it behaves when provided with malicious or inadvertently harmful input:184 - An input may be malicious when the input is clearly designed to produce an unsafe or harmful output-- for example, asking a text generation model to generate a hateful rant about a particular religion.185 - An input is inadvertently harmful when the input itself may be innocuous, but produces harmful output -- for example, asking a text generation model to describe a person of a particular ethnicity and receiving a racist output.186 - What distinguishes an adversarial test from a standard evaluation is the187 composition of the data used for testing. For adversarial tests, select188 test data that is most likely to elicit problematic output from189 the model. This means probing the model's behavior for all the types of190 harms that are possible, including rare or unusual examples and191 edge-cases that are relevant to safety policies. It should also include192 diversity in the different dimensions of a sentence such as structure,193 meaning and length. You can refer to the [Google's Responsible AI194 practices in195 fairness](https://ai.google/responsibilities/responsible-ai-practices/?category=fairness)196 for more details on what to consider when building a test dataset.197 **Advanced tips:**198199 - Use [automated testing](https://www.deepmind.com/blog/red-teaming-language-models-with-language-models)200 instead of the traditional method of enlisting people in 'red201 teams' to try and break your application. In automated testing,202 the 'red team' is another language model that finds input text203 that elicit harmful outputs from the model being tested.204205 > [!NOTE]206 > **Note:** LLMs are known to sometimes produce different outputs for the same input prompt. Multiple rounds of testing may be needed to catch more of the problematic outputs.207208## Monitor for problems209210No matter how much you test and mitigate, you can never guarantee perfection, so211plan upfront how you'll spot and deal with problems that arise. Common212approaches include setting up a monitored channel for users to share feedback213(e.g., thumbs up/down rating) and running a user study to proactively solicit214feedback from a diverse mix of users --- especially valuable if usage patterns are215different to expectations.216217### Advanced tips218219- When users give feedback to AI products, it can greatly improve the AI performance and the user experience over time by, for example, helping you choose better examples for prompt tuning. The [Feedback and Control chapter](https://pair.withgoogle.com/chapter/feedback-controls/) in [Google's People and AI guidebook](https://pair.withgoogle.com/guidebook/chapters) highlights key considerations to take into account when designing feedback mechanisms.220221## Next steps222223- Refer to the [safety settings](https://ai.google.dev/gemini-api/docs/safety-settings) guide to learn about the adjustable safety settings available through the Gemini API.224- See the [intro to prompting](https://ai.google.dev/gemini-api/docs/prompting-intro) to get started writing your first prompts.