Repository Public
1<br />23<br />45The Live API enables low-latency, real-time voice and video interactions with Gemini. It processes continuous streams of audio, video, or text to deliver immediate, human-like spoken responses, creating a natural conversational experience for your users.67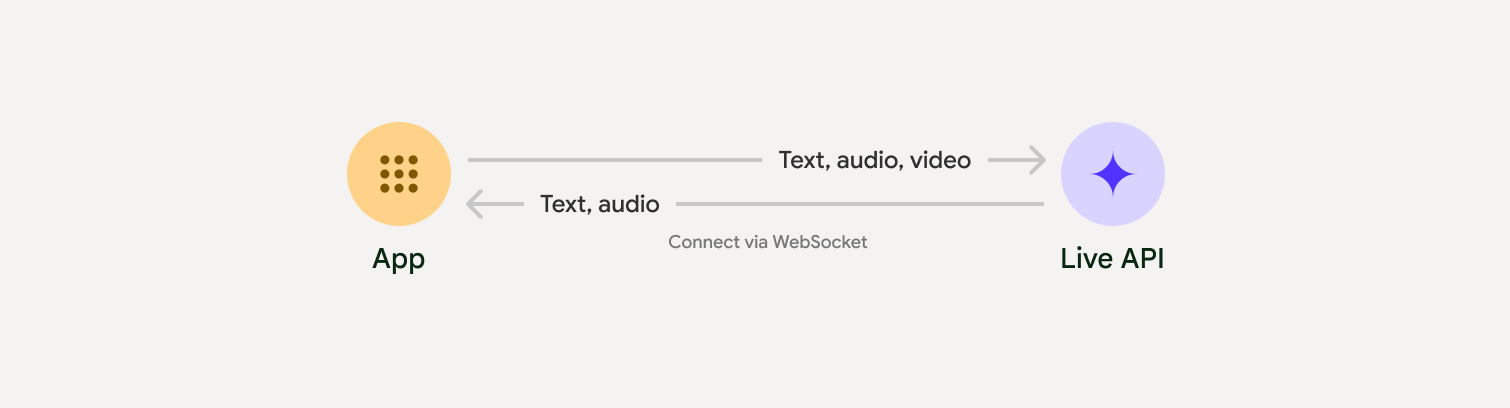89Live API offers a comprehensive set of features such as[Voice Activity Detection](https://ai.google.dev/gemini-api/docs/live-guide#interruptions),[tool use and function calling](https://ai.google.dev/gemini-api/docs/live-tools),[session management](https://ai.google.dev/gemini-api/docs/live-session)(for managing long running conversations) and[ephemeral tokens](https://ai.google.dev/gemini-api/docs/ephemeral-tokens)(for secure client-sided authentication).1011This page gets you up and running with examples and basic code samples.1213[Try the Live API in Google AI Studiomic](https://aistudio.google.com/live)1415## Choose an implementation approach1617When integrating with Live API, you'll need to choose one of the following implementation approaches:1819- **Server-to-server** : Your backend connects to the Live API using[WebSockets](https://developer.mozilla.org/en-US/docs/Web/API/WebSockets_API). Typically, your client sends stream data (audio, video, text) to your server, which then forwards it to the Live API.20- **Client-to-server** : Your frontend code connects directly to the Live API using[WebSockets](https://developer.mozilla.org/en-US/docs/Web/API/WebSockets_API)to stream data, bypassing your backend.2122**Note:** Client-to-server generally offers better performance for streaming audio and video, since it bypasses the need to send the stream to your backend first. It's also easier to set up since you don't need to implement a proxy that sends data from your client to your server and then your server to the API. However, for production environments, in order to mitigate security risks, we recommend using[ephemeral tokens](https://ai.google.dev/gemini-api/docs/ephemeral-tokens)instead of standard API keys. 2324## Partner integrations2526To streamline the development of real-time audio and video apps, you can use a third-party integration that supports the Gemini Live API over WebRTC or WebSockets. 27[Pipecat by Daily28Create a real-time AI chatbot using Gemini Live and Pipecat.](https://docs.pipecat.ai/guides/features/gemini-live)[LiveKit29Use the Gemini Live API with LiveKit Agents.](https://docs.livekit.io/agents/models/realtime/plugins/gemini/)[Fishjam by Software Mansion30Create live video and audio streaming applications with Fishjam.](https://docs.fishjam.io/tutorials/gemini-live-integration)[Agent Development Kit (ADK)31Implement the Live API with Agent Development Kit (ADK).](https://google.github.io/adk-docs/streaming/)[Vision Agents by Stream32Build real-time voice and video AI applications with Vision Agents.](https://visionagents.ai/integrations/gemini)[Voximplant33Connect inbound and outbound calls to Live API with Voximplant.](https://voximplant.com/products/gemini-client)3435## Get started3637Microphone streamAudio file stream3839This server-side example**streams audio from the microphone** and plays the returned audio. For complete end-to-end examples including a client application, see[Example applications](https://ai.google.dev/gemini-api/docs/live#example-applications).4041The input audio format should be in 16-bit PCM, 16kHz, mono format, and the received audio uses a sample rate of 24kHz. 4243### Python4445Install helpers for audio streaming. Additional system-level dependencies (e.g.`portaudio`) might be required. Refer to the[PyAudio docs](https://pypi.org/project/PyAudio/)for detailed installation steps. 4647 pip install pyaudio4849**Note:** **Use headphones**. This script uses the system default audio input and output, which often won't include echo cancellation. To prevent the model from interrupting itself, use headphones. 5051 import asyncio52 from google import genai53 import pyaudio5455 client = genai.Client()5657 # --- pyaudio config ---58 FORMAT = pyaudio.paInt1659 CHANNELS = 160 SEND_SAMPLE_RATE = 1600061 RECEIVE_SAMPLE_RATE = 2400062 CHUNK_SIZE = 10246364 pya = pyaudio.PyAudio()6566 # --- Live API config ---67 MODEL = "gemini-2.5-flash-native-audio-preview-12-2025"68 CONFIG = {69 "response_modalities": ["AUDIO"],70 "system_instruction": "You are a helpful and friendly AI assistant.",71 }7273 audio_queue_output = asyncio.Queue()74 audio_queue_mic = asyncio.Queue(maxsize=5)75 audio_stream = None7677 async def listen_audio():78 """Listens for audio and puts it into the mic audio queue."""79 global audio_stream80 mic_info = pya.get_default_input_device_info()81 audio_stream = await asyncio.to_thread(82 pya.open,83 format=FORMAT,84 channels=CHANNELS,85 rate=SEND_SAMPLE_RATE,86 input=True,87 input_device_index=mic_info["index"],88 frames_per_buffer=CHUNK_SIZE,89 )90 kwargs = {"exception_on_overflow": False} if __debug__ else {}91 while True:92 data = await asyncio.to_thread(audio_stream.read, CHUNK_SIZE, **kwargs)93 await audio_queue_mic.put({"data": data, "mime_type": "audio/pcm"})9495 async def send_realtime(session):96 """Sends audio from the mic audio queue to the GenAI session."""97 while True:98 msg = await audio_queue_mic.get()99 await session.send_realtime_input(audio=msg)100101 async def receive_audio(session):102 """Receives responses from GenAI and puts audio data into the speaker audio queue."""103 while True:104 turn = session.receive()105 async for response in turn:106 if (response.server_content and response.server_content.model_turn):107 for part in response.server_content.model_turn.parts:108 if part.inline_data and isinstance(part.inline_data.data, bytes):109 audio_queue_output.put_nowait(part.inline_data.data)110111 # Empty the queue on interruption to stop playback112 while not audio_queue_output.empty():113 audio_queue_output.get_nowait()114115 async def play_audio():116 """Plays audio from the speaker audio queue."""117 stream = await asyncio.to_thread(118 pya.open,119 format=FORMAT,120 channels=CHANNELS,121 rate=RECEIVE_SAMPLE_RATE,122 output=True,123 )124 while True:125 bytestream = await audio_queue_output.get()126 await asyncio.to_thread(stream.write, bytestream)127128 async def run():129 """Main function to run the audio loop."""130 try:131 async with client.aio.live.connect(132 model=MODEL, config=CONFIG133 ) as live_session:134 print("Connected to Gemini. Start speaking!")135 async with asyncio.TaskGroup() as tg:136 tg.create_task(send_realtime(live_session))137 tg.create_task(listen_audio())138 tg.create_task(receive_audio(live_session))139 tg.create_task(play_audio())140 except asyncio.CancelledError:141 pass142 finally:143 if audio_stream:144 audio_stream.close()145 pya.terminate()146 print("\nConnection closed.")147148 if __name__ == "__main__":149 try:150 asyncio.run(run())151 except KeyboardInterrupt:152 print("Interrupted by user.")153154### JavaScript155156Install helpers for audio streaming. Additional system-level dependencies might be required (`sox`for Mac/Windows or`ALSA`for Linux). Refer to the[speaker](https://www.npmjs.com/package/speaker)and[mic](https://www.npmjs.com/package/mic)docs for detailed installation steps. 157158 npm install mic speaker159160**Note:** **Use headphones**. This script uses the system default audio input and output, which often won't include echo cancellation. To prevent the model from interrupting itself, use headphones. 161162 import { GoogleGenAI, Modality } from '@google/genai';163 import mic from 'mic';164 import Speaker from 'speaker';165166 const ai = new GoogleGenAI({});167 // WARNING: Do not use API keys in client-side (browser based) applications168 // Consider using Ephemeral Tokens instead169 // More information at: https://ai.google.dev/gemini-api/docs/ephemeral-tokens170171 // --- Live API config ---172 const model = 'gemini-2.5-flash-native-audio-preview-12-2025';173 const config = {174 responseModalities: [Modality.AUDIO],175 systemInstruction: "You are a helpful and friendly AI assistant.",176 };177178 async function live() {179 const responseQueue = [];180 const audioQueue = [];181 let speaker;182183 async function waitMessage() {184 while (responseQueue.length === 0) {185 await new Promise((resolve) => setImmediate(resolve));186 }187 return responseQueue.shift();188 }189190 function createSpeaker() {191 if (speaker) {192 process.stdin.unpipe(speaker);193 speaker.end();194 }195 speaker = new Speaker({196 channels: 1,197 bitDepth: 16,198 sampleRate: 24000,199 });200 speaker.on('error', (err) => console.error('Speaker error:', err));201 process.stdin.pipe(speaker);202 }203204 async function messageLoop() {205 // Puts incoming messages in the audio queue.206 while (true) {207 const message = await waitMessage();208 if (message.serverContent && message.serverContent.interrupted) {209 // Empty the queue on interruption to stop playback210 audioQueue.length = 0;211 continue;212 }213 if (message.serverContent && message.serverContent.modelTurn && message.serverContent.modelTurn.parts) {214 for (const part of message.serverContent.modelTurn.parts) {215 if (part.inlineData && part.inlineData.data) {216 audioQueue.push(Buffer.from(part.inlineData.data, 'base64'));217 }218 }219 }220 }221 }222223 async function playbackLoop() {224 // Plays audio from the audio queue.225 while (true) {226 if (audioQueue.length === 0) {227 if (speaker) {228 // Destroy speaker if no more audio to avoid warnings from speaker library229 process.stdin.unpipe(speaker);230 speaker.end();231 speaker = null;232 }233 await new Promise((resolve) => setImmediate(resolve));234 } else {235 if (!speaker) createSpeaker();236 const chunk = audioQueue.shift();237 await new Promise((resolve) => {238 speaker.write(chunk, () => resolve());239 });240 }241 }242 }243244 // Start loops245 messageLoop();246 playbackLoop();247248 // Connect to Gemini Live API249 const session = await ai.live.connect({250 model: model,251 config: config,252 callbacks: {253 onopen: () => console.log('Connected to Gemini Live API'),254 onmessage: (message) => responseQueue.push(message),255 onerror: (e) => console.error('Error:', e.message),256 onclose: (e) => console.log('Closed:', e.reason),257 },258 });259260 // Setup Microphone for input261 const micInstance = mic({262 rate: '16000',263 bitwidth: '16',264 channels: '1',265 });266 const micInputStream = micInstance.getAudioStream();267268 micInputStream.on('data', (data) => {269 // API expects base64 encoded PCM data270 session.sendRealtimeInput({271 audio: {272 data: data.toString('base64'),273 mimeType: "audio/pcm;rate=16000"274 }275 });276 });277278 micInputStream.on('error', (err) => {279 console.error('Microphone error:', err);280 });281282 micInstance.start();283 console.log('Microphone started. Speak now...');284 }285286 live().catch(console.error);287288## Example applications289290Check out the following example applications that illustrate how to use Live API for end-to-end use cases:291292- [Live audio starter app](https://aistudio.google.com/apps/bundled/live_audio?showPreview=true&showCode=true&showAssistant=false)on AI Studio, using JavaScript libraries to connect to Live API and stream bidirectional audio through your microphone and speakers.293- See the[Partner integrations](https://ai.google.dev/gemini-api/docs/live#partner-integrations)for additional examples and getting started guides.294295## What's next296297- Read the full Live API[Capabilities](https://ai.google.dev/gemini-api/docs/live-guide)guide for key capabilities and configurations; including Voice Activity Detection and native audio features.298- Read the[Tool use](https://ai.google.dev/gemini-api/docs/live-tools)guide to learn how to integrate Live API with tools and function calling.299- Read the[Session management](https://ai.google.dev/gemini-api/docs/live-session)guide for managing long running conversations.300- Read the[Ephemeral tokens](https://ai.google.dev/gemini-api/docs/ephemeral-tokens)guide for secure authentication in[client-to-server](https://ai.google.dev/gemini-api/docs/live#implementation-approach)applications.301- For more information about the underlying WebSockets API, see the[WebSockets API reference](https://ai.google.dev/api/live).